Does Qwen 3.5 live up to the hype?
I tested 9 local LLMs on a Claude Code skill I actually use every day. Not a coding benchmark. A real multi-step agentic task described in natural language a...
Tap a slide to expand
I tested 9 local LLMs on a Claude Code skill I actually use every day. Not a coding benchmark. A real multi-step agentic task described in natural language as a markdown file.
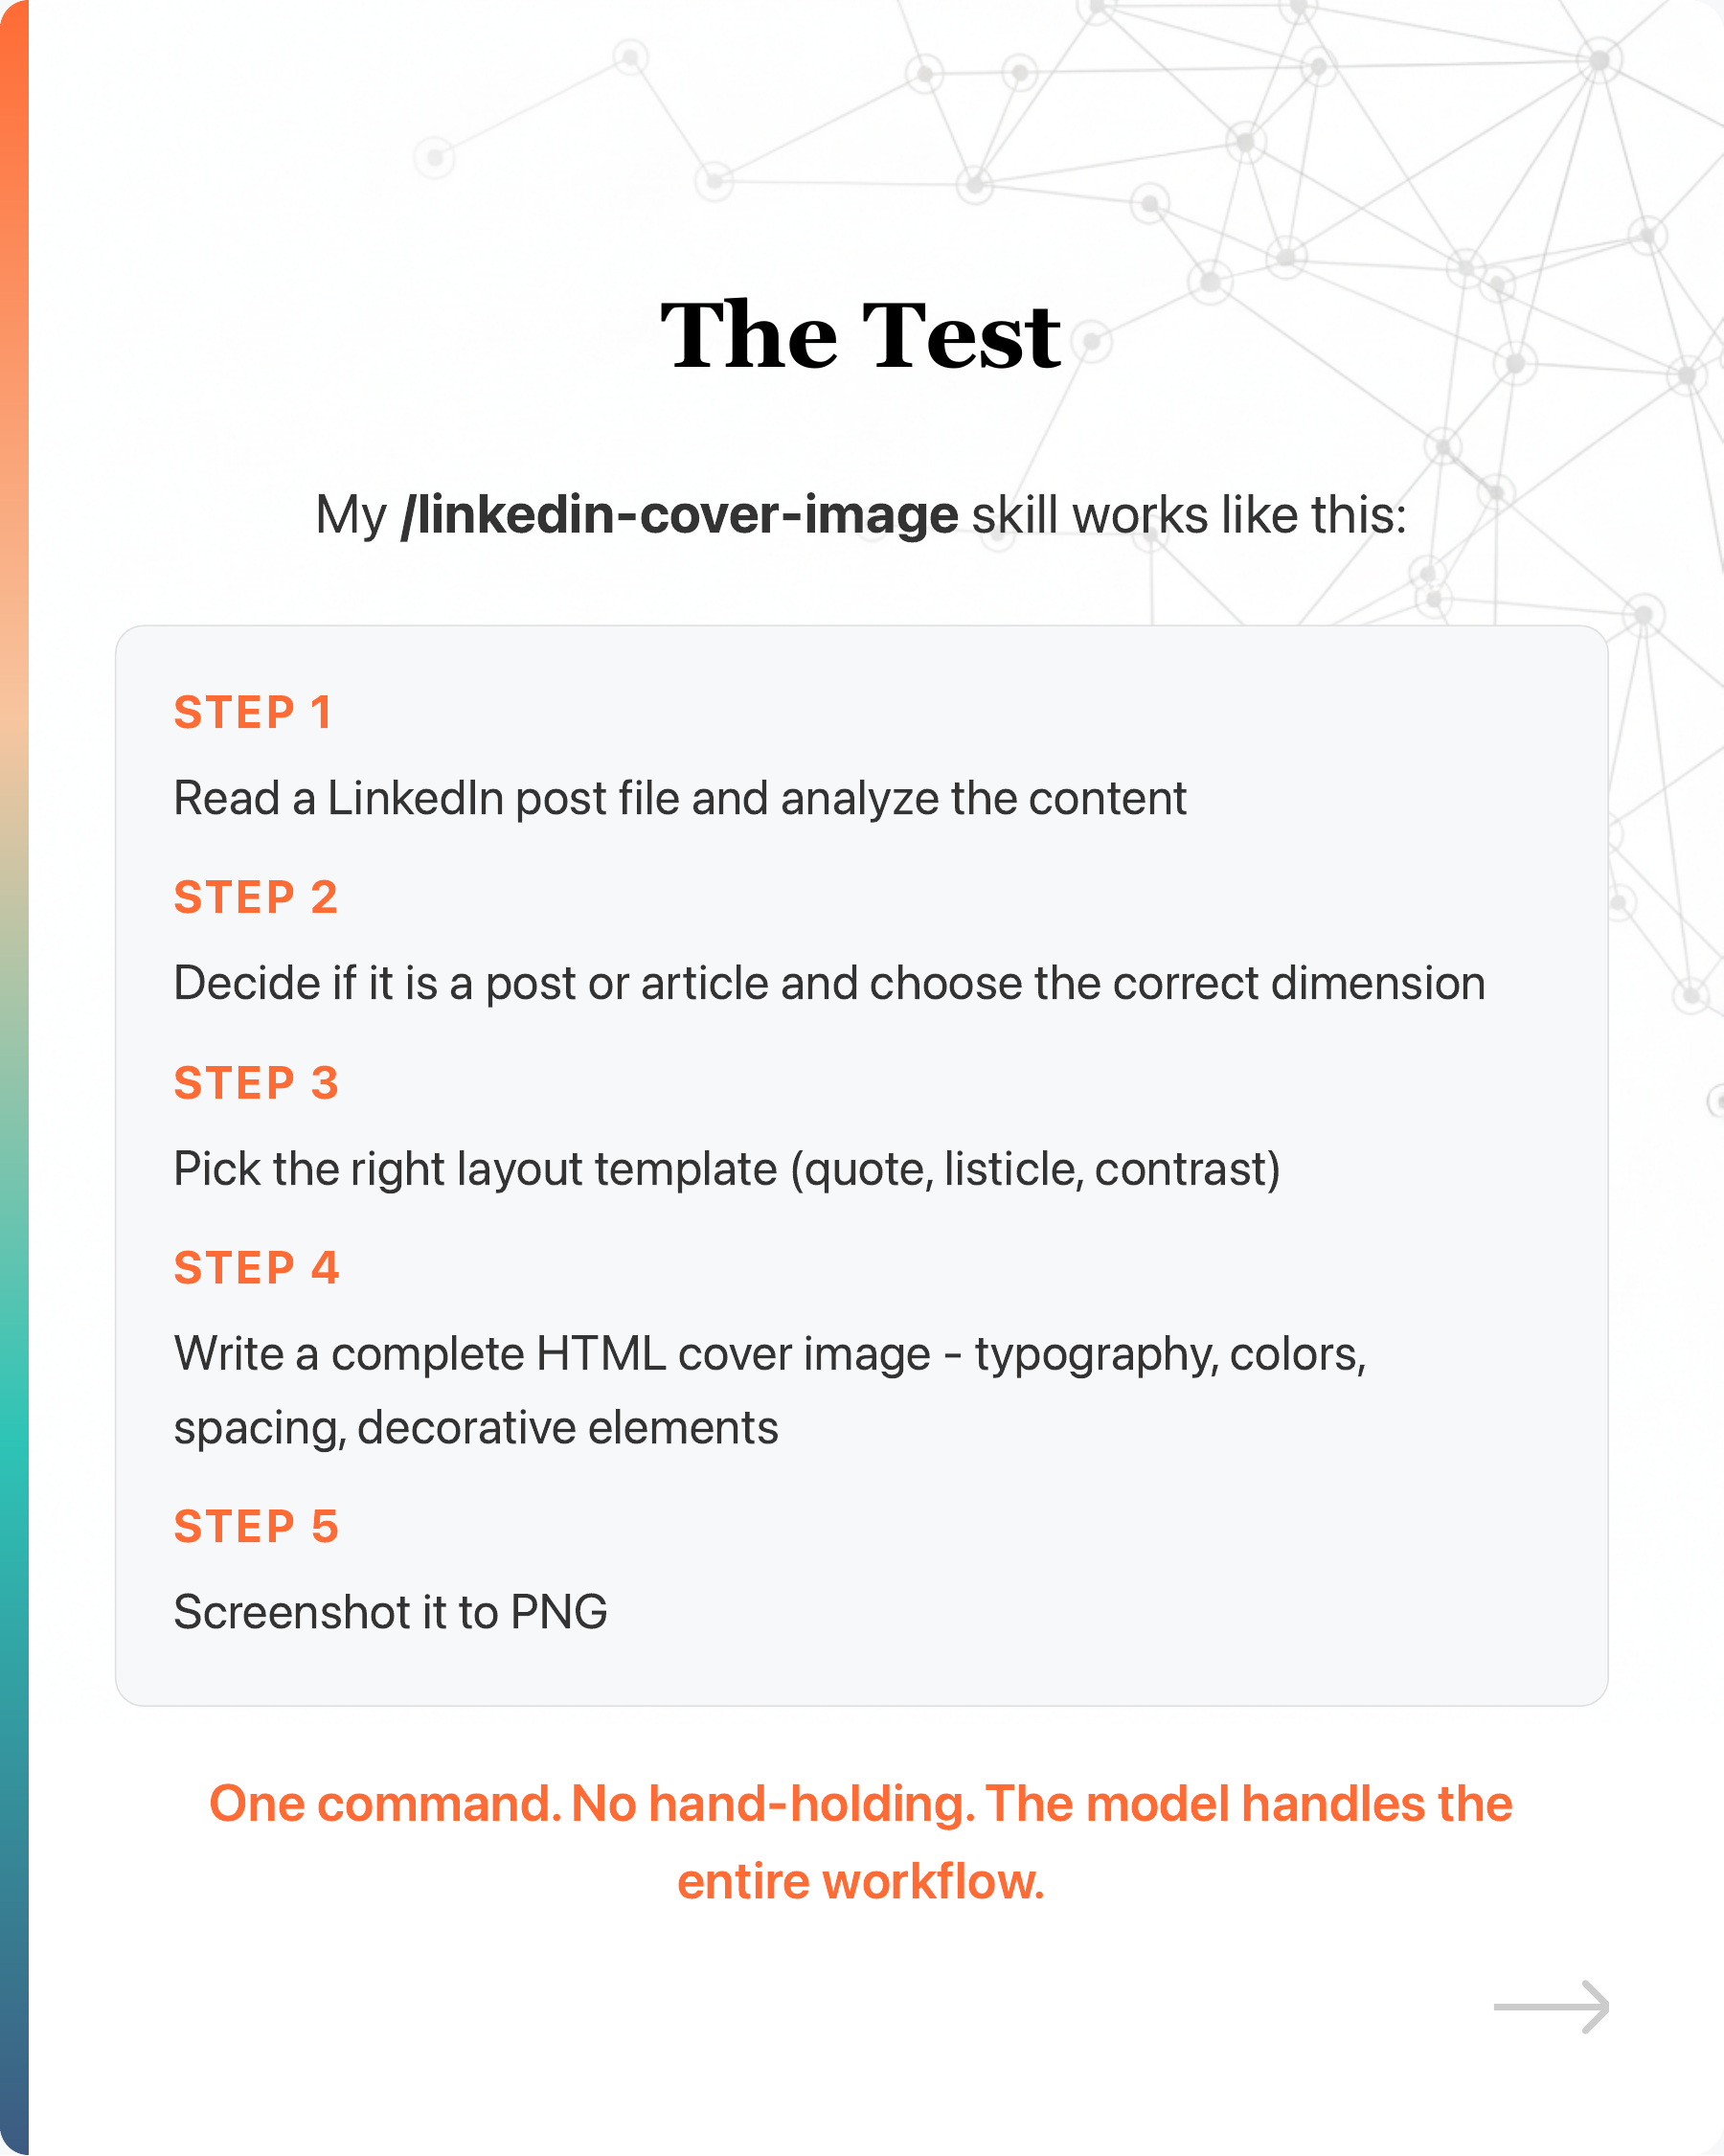
My /linkedin-cover-image skill works like this:
- Read a LinkedIn post file and analyze the content
- Decide if it is a post or article and choose the correct dimension
- Pick the right layout template (quote, listicle, contrast)
- Write a complete HTML cover image - typography, colors, spacing, decorative elements
- Screenshot it to PNG
One command. No hand-holding. The model handles the entire workflow.
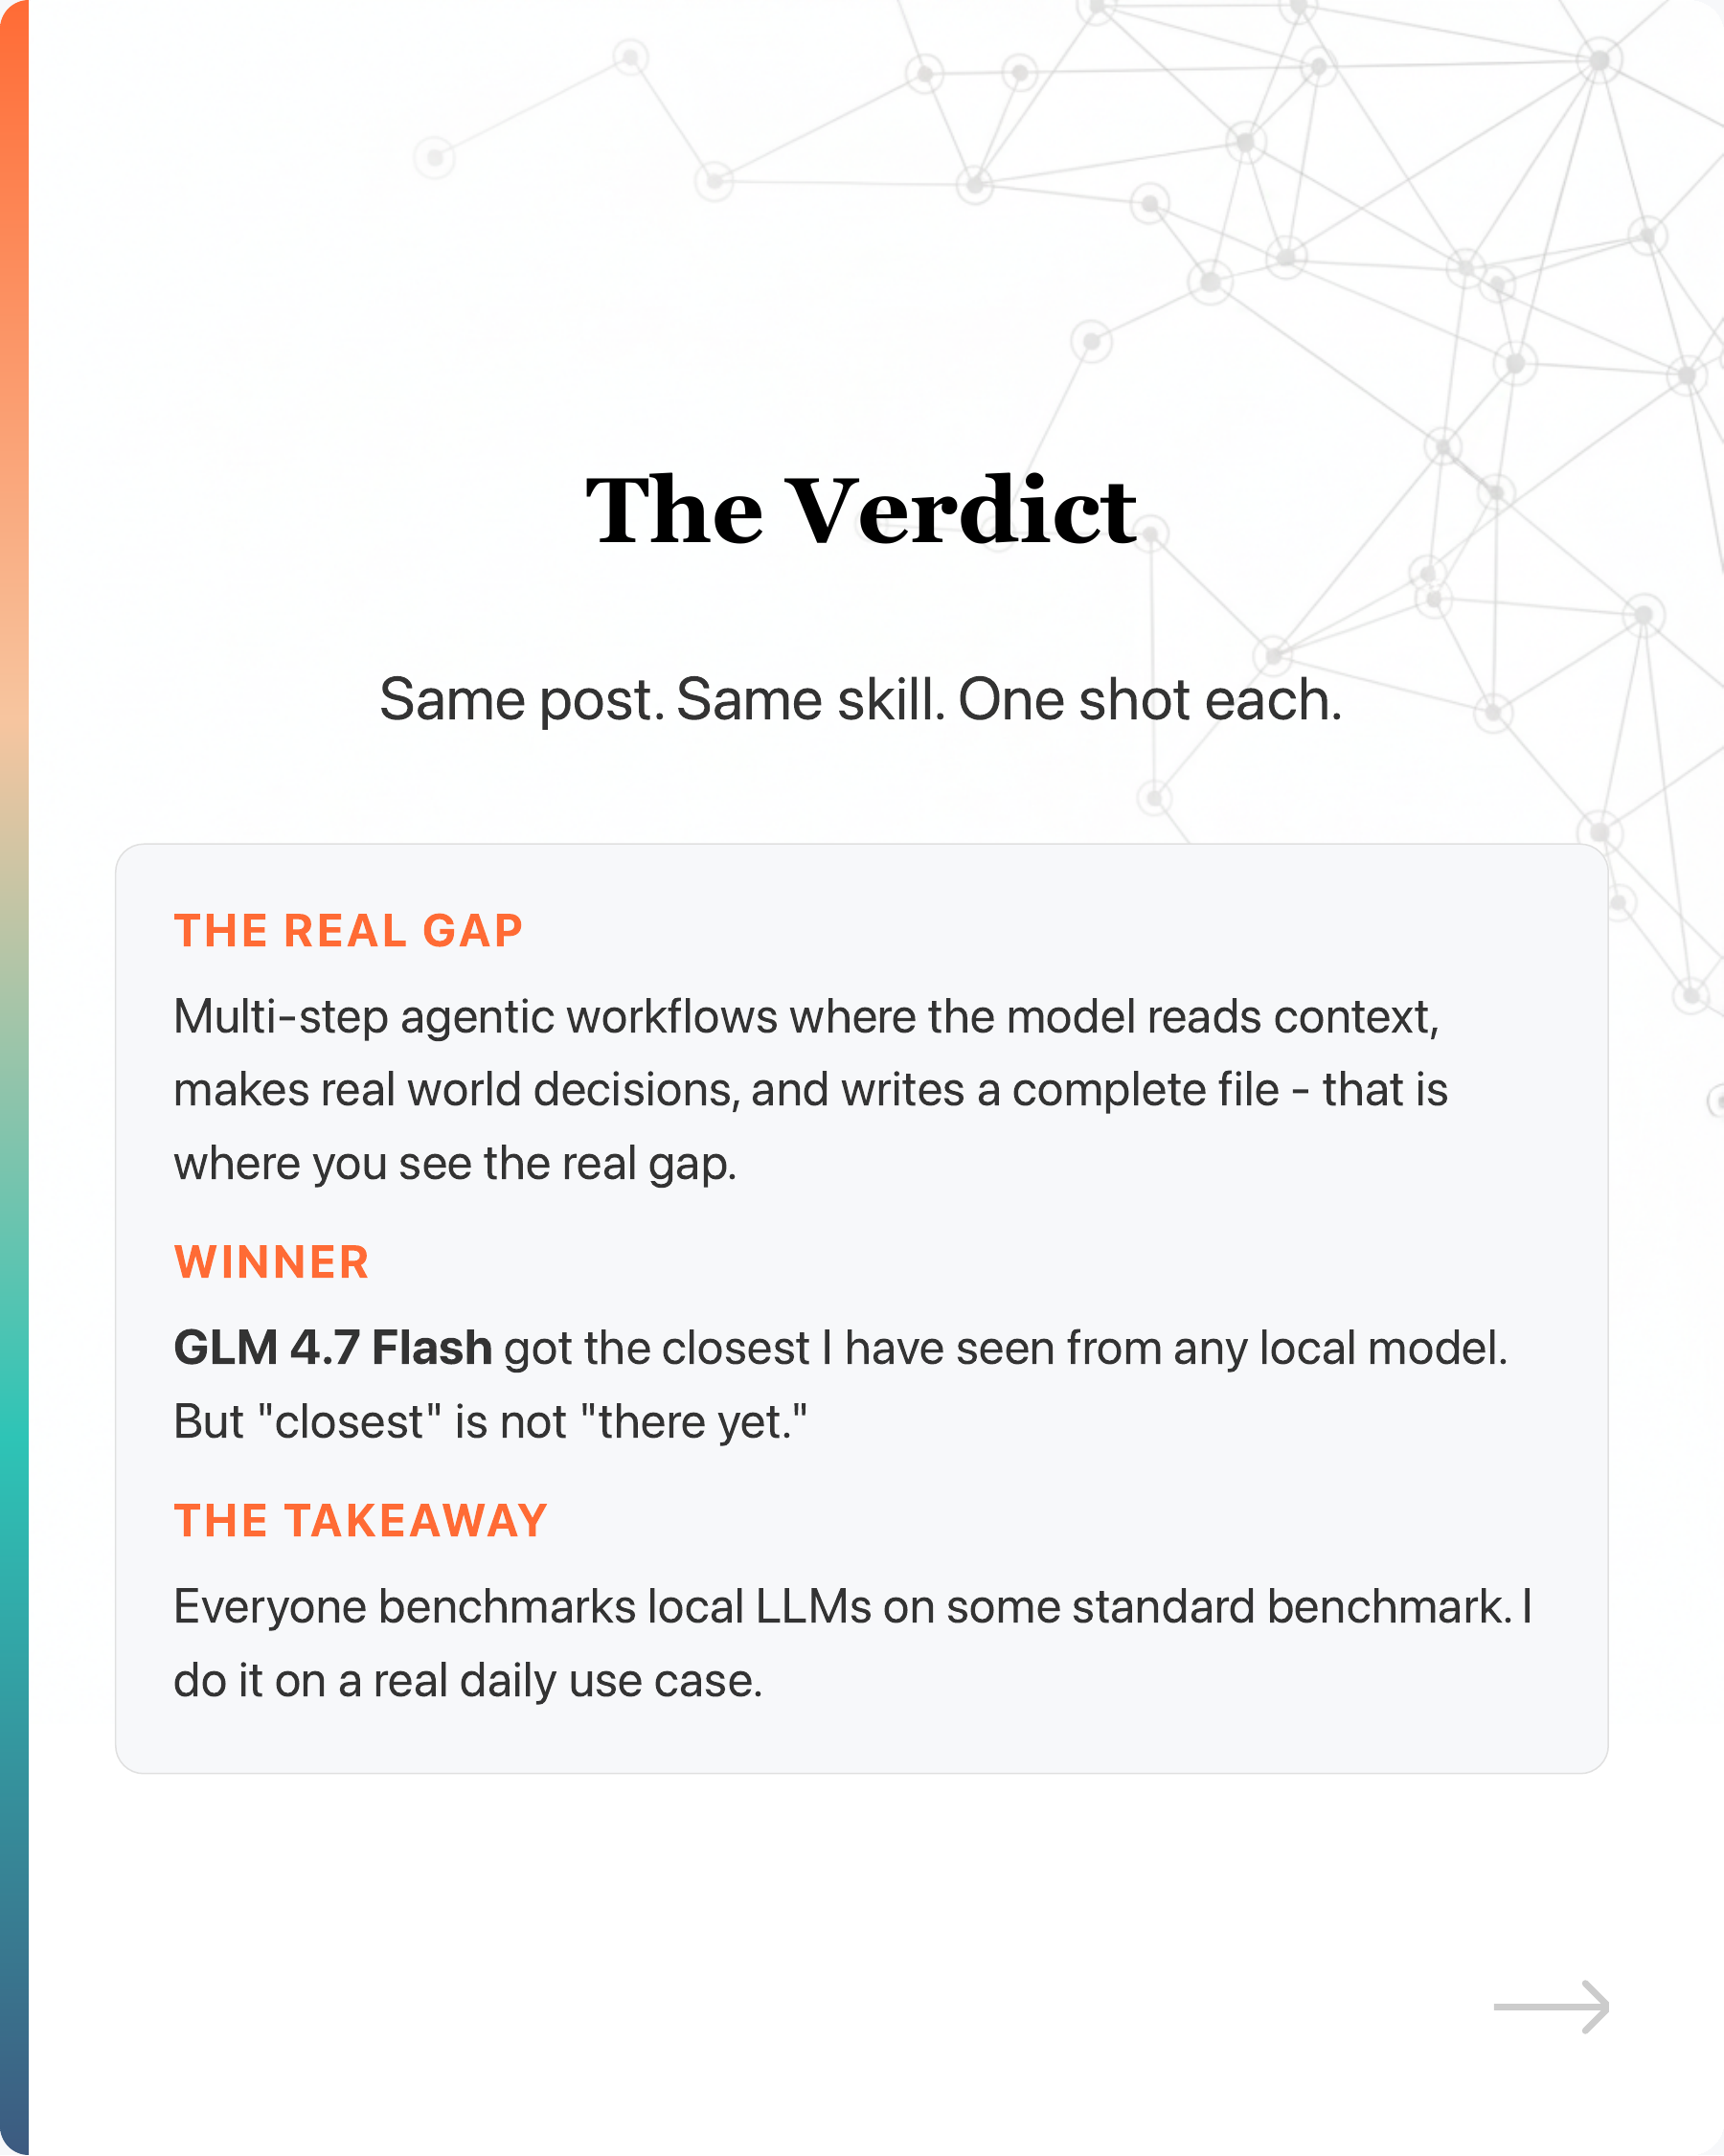
Same post. Same skill. One shot each. All results in the images.
—
Out of 9 models (5 usable / 2 issues / 2 failed):
Usable:
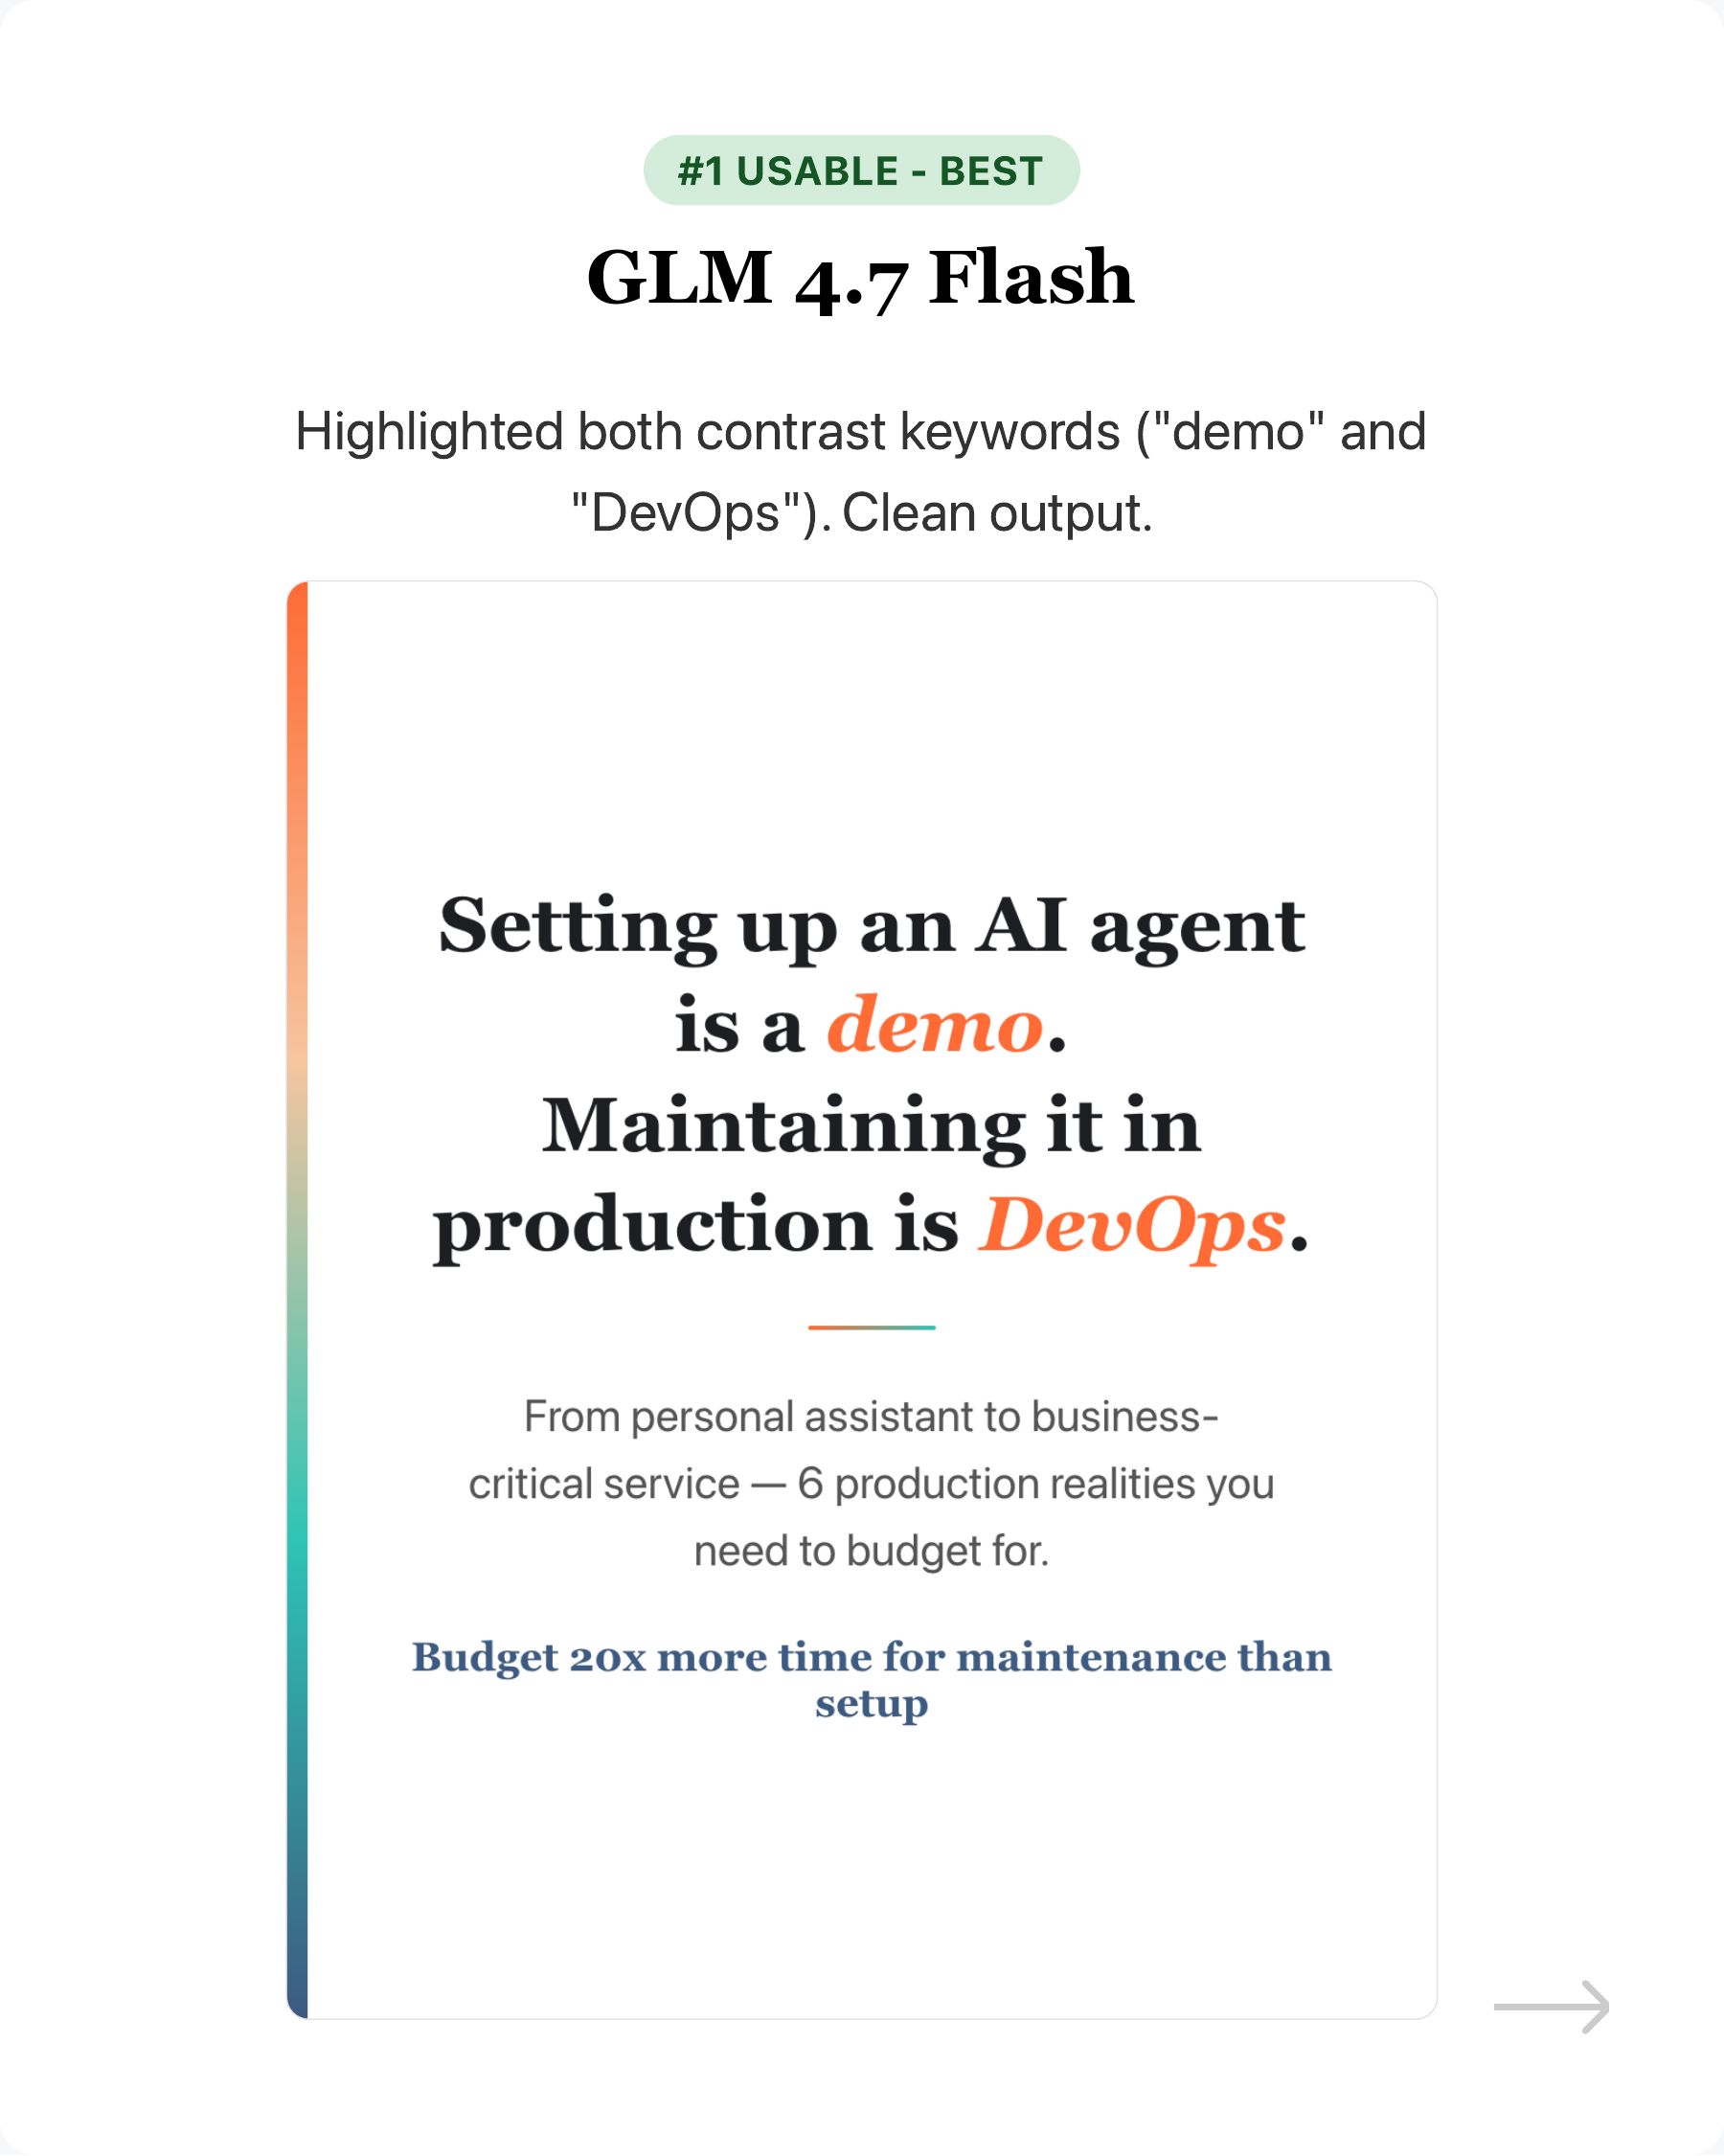
- GLM 4.7 Flash - Best. Highlighted both contrast keywords (“demo” and “DevOps”). Clean output.
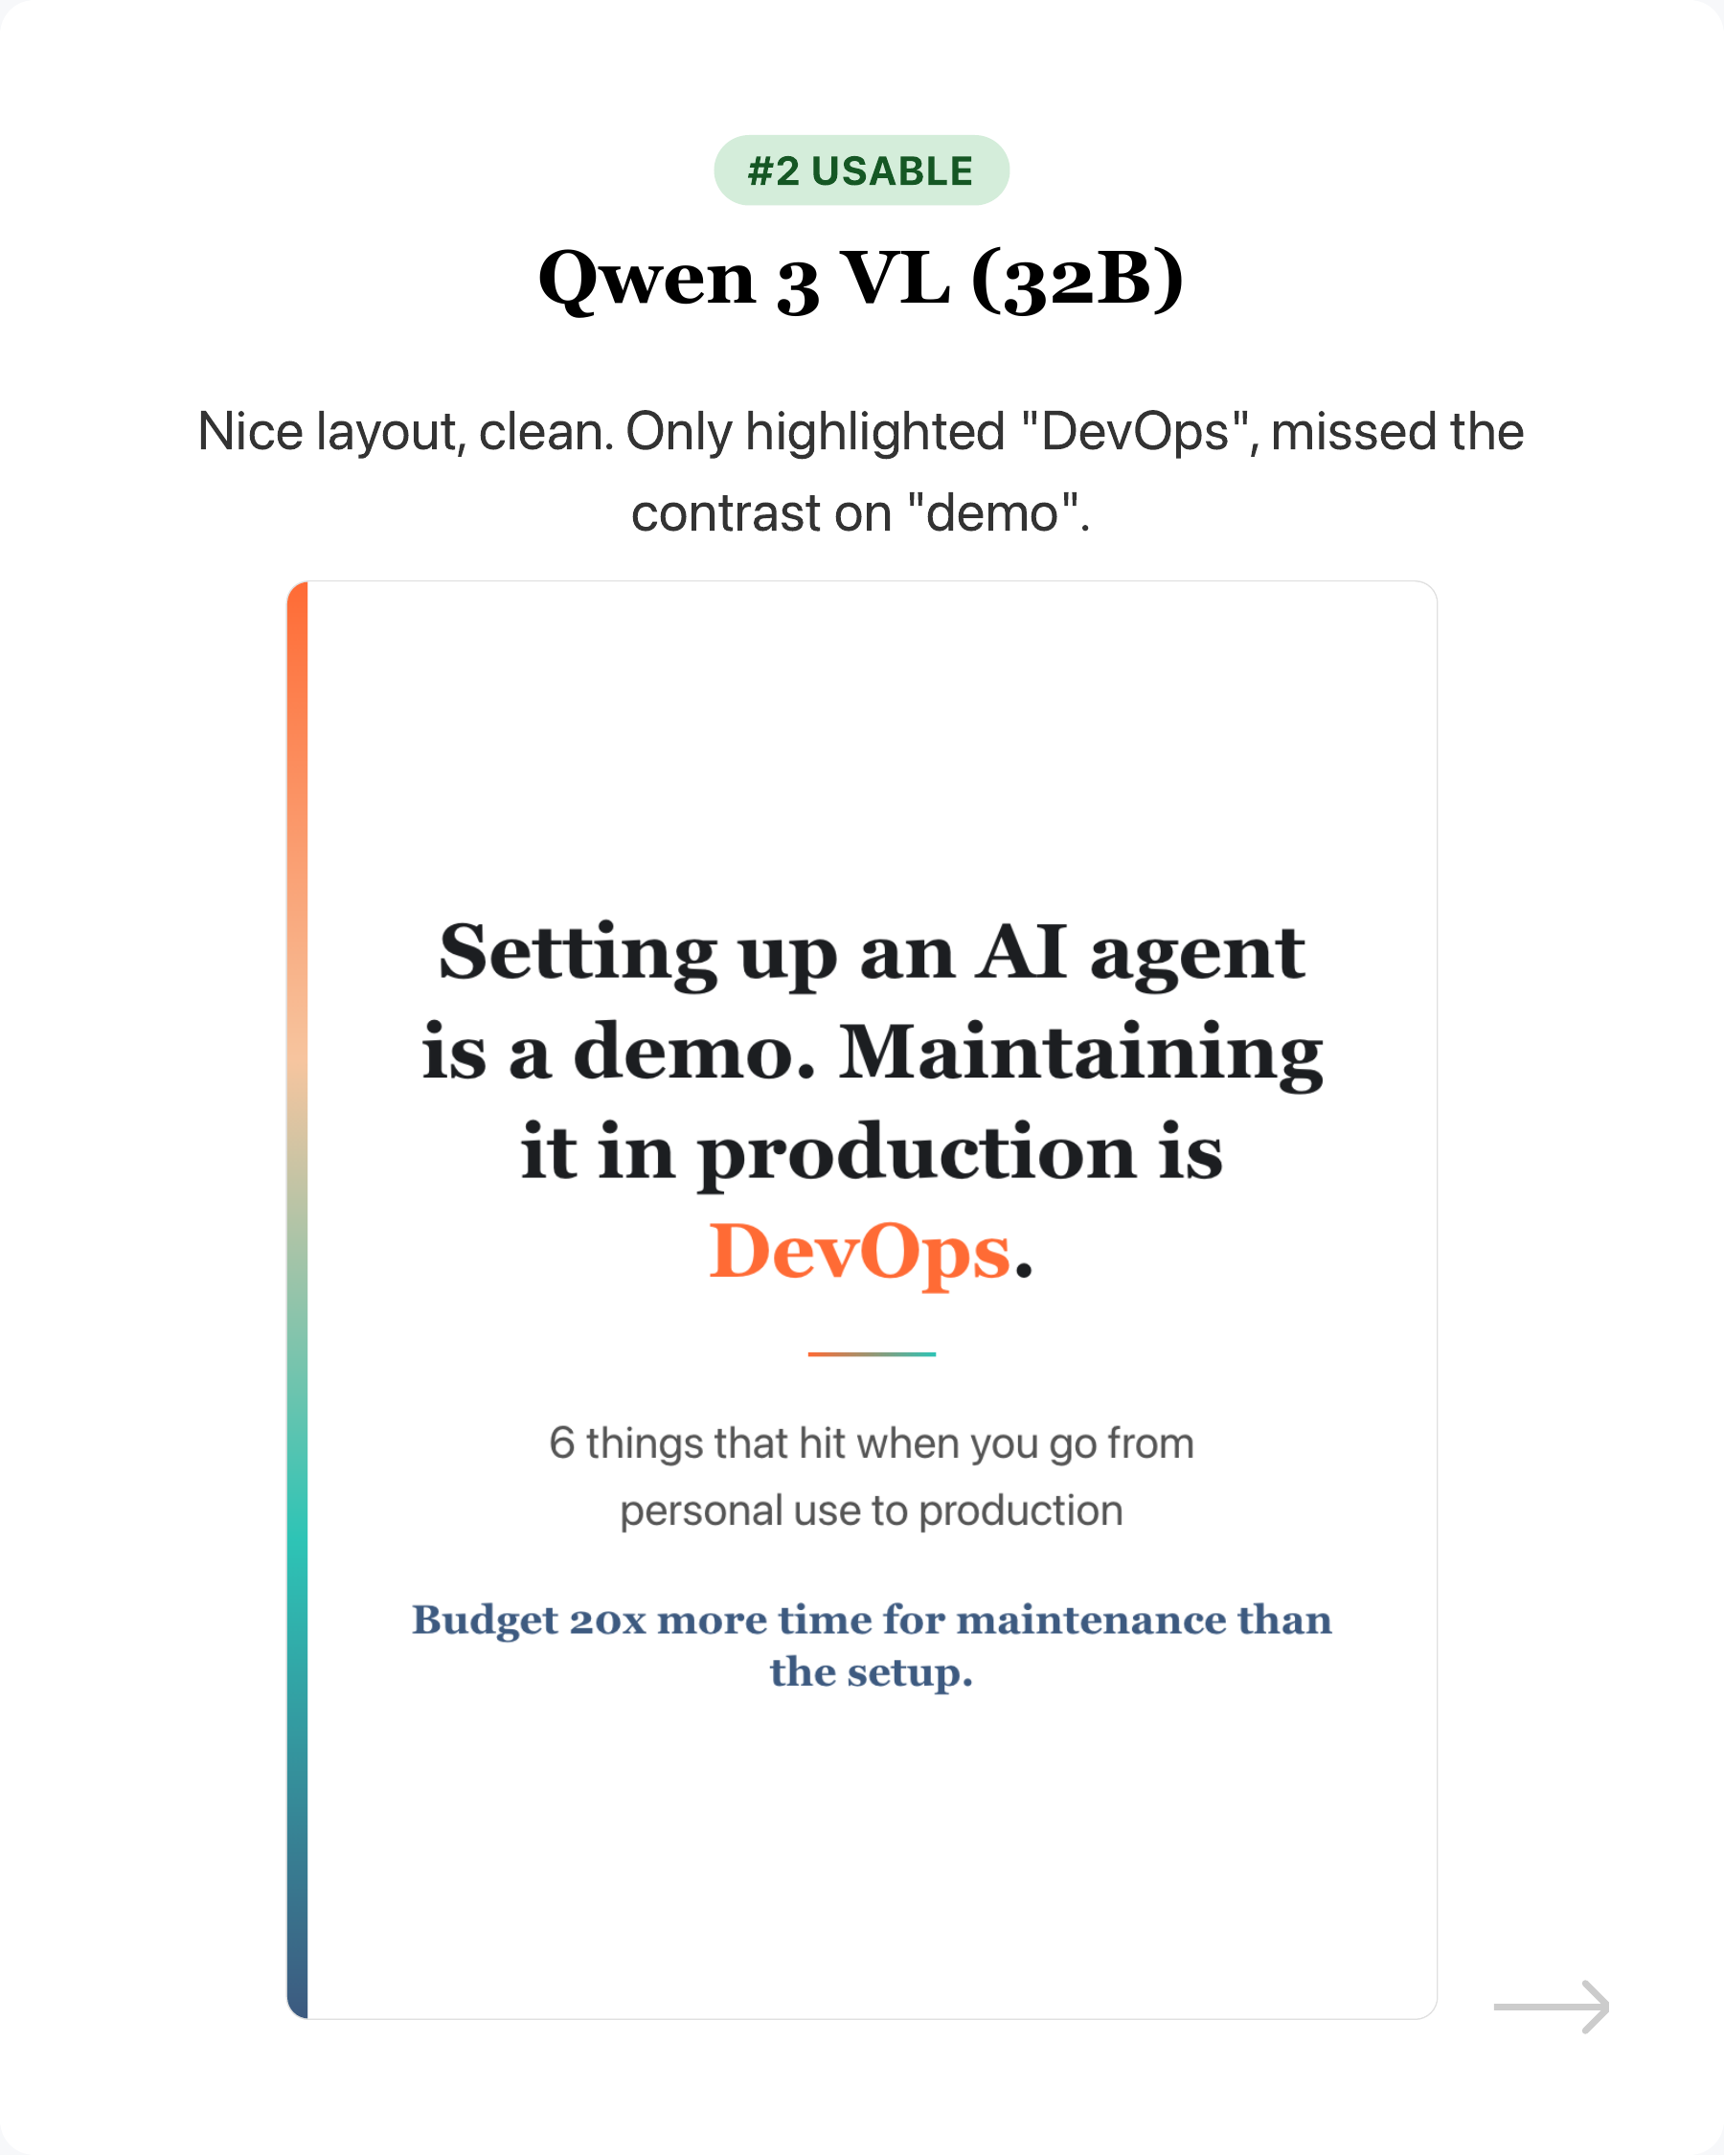
- Qwen 3 VL (32B) - Nice layout, clean. Only highlighted “DevOps”, missed the contrast on “demo”.
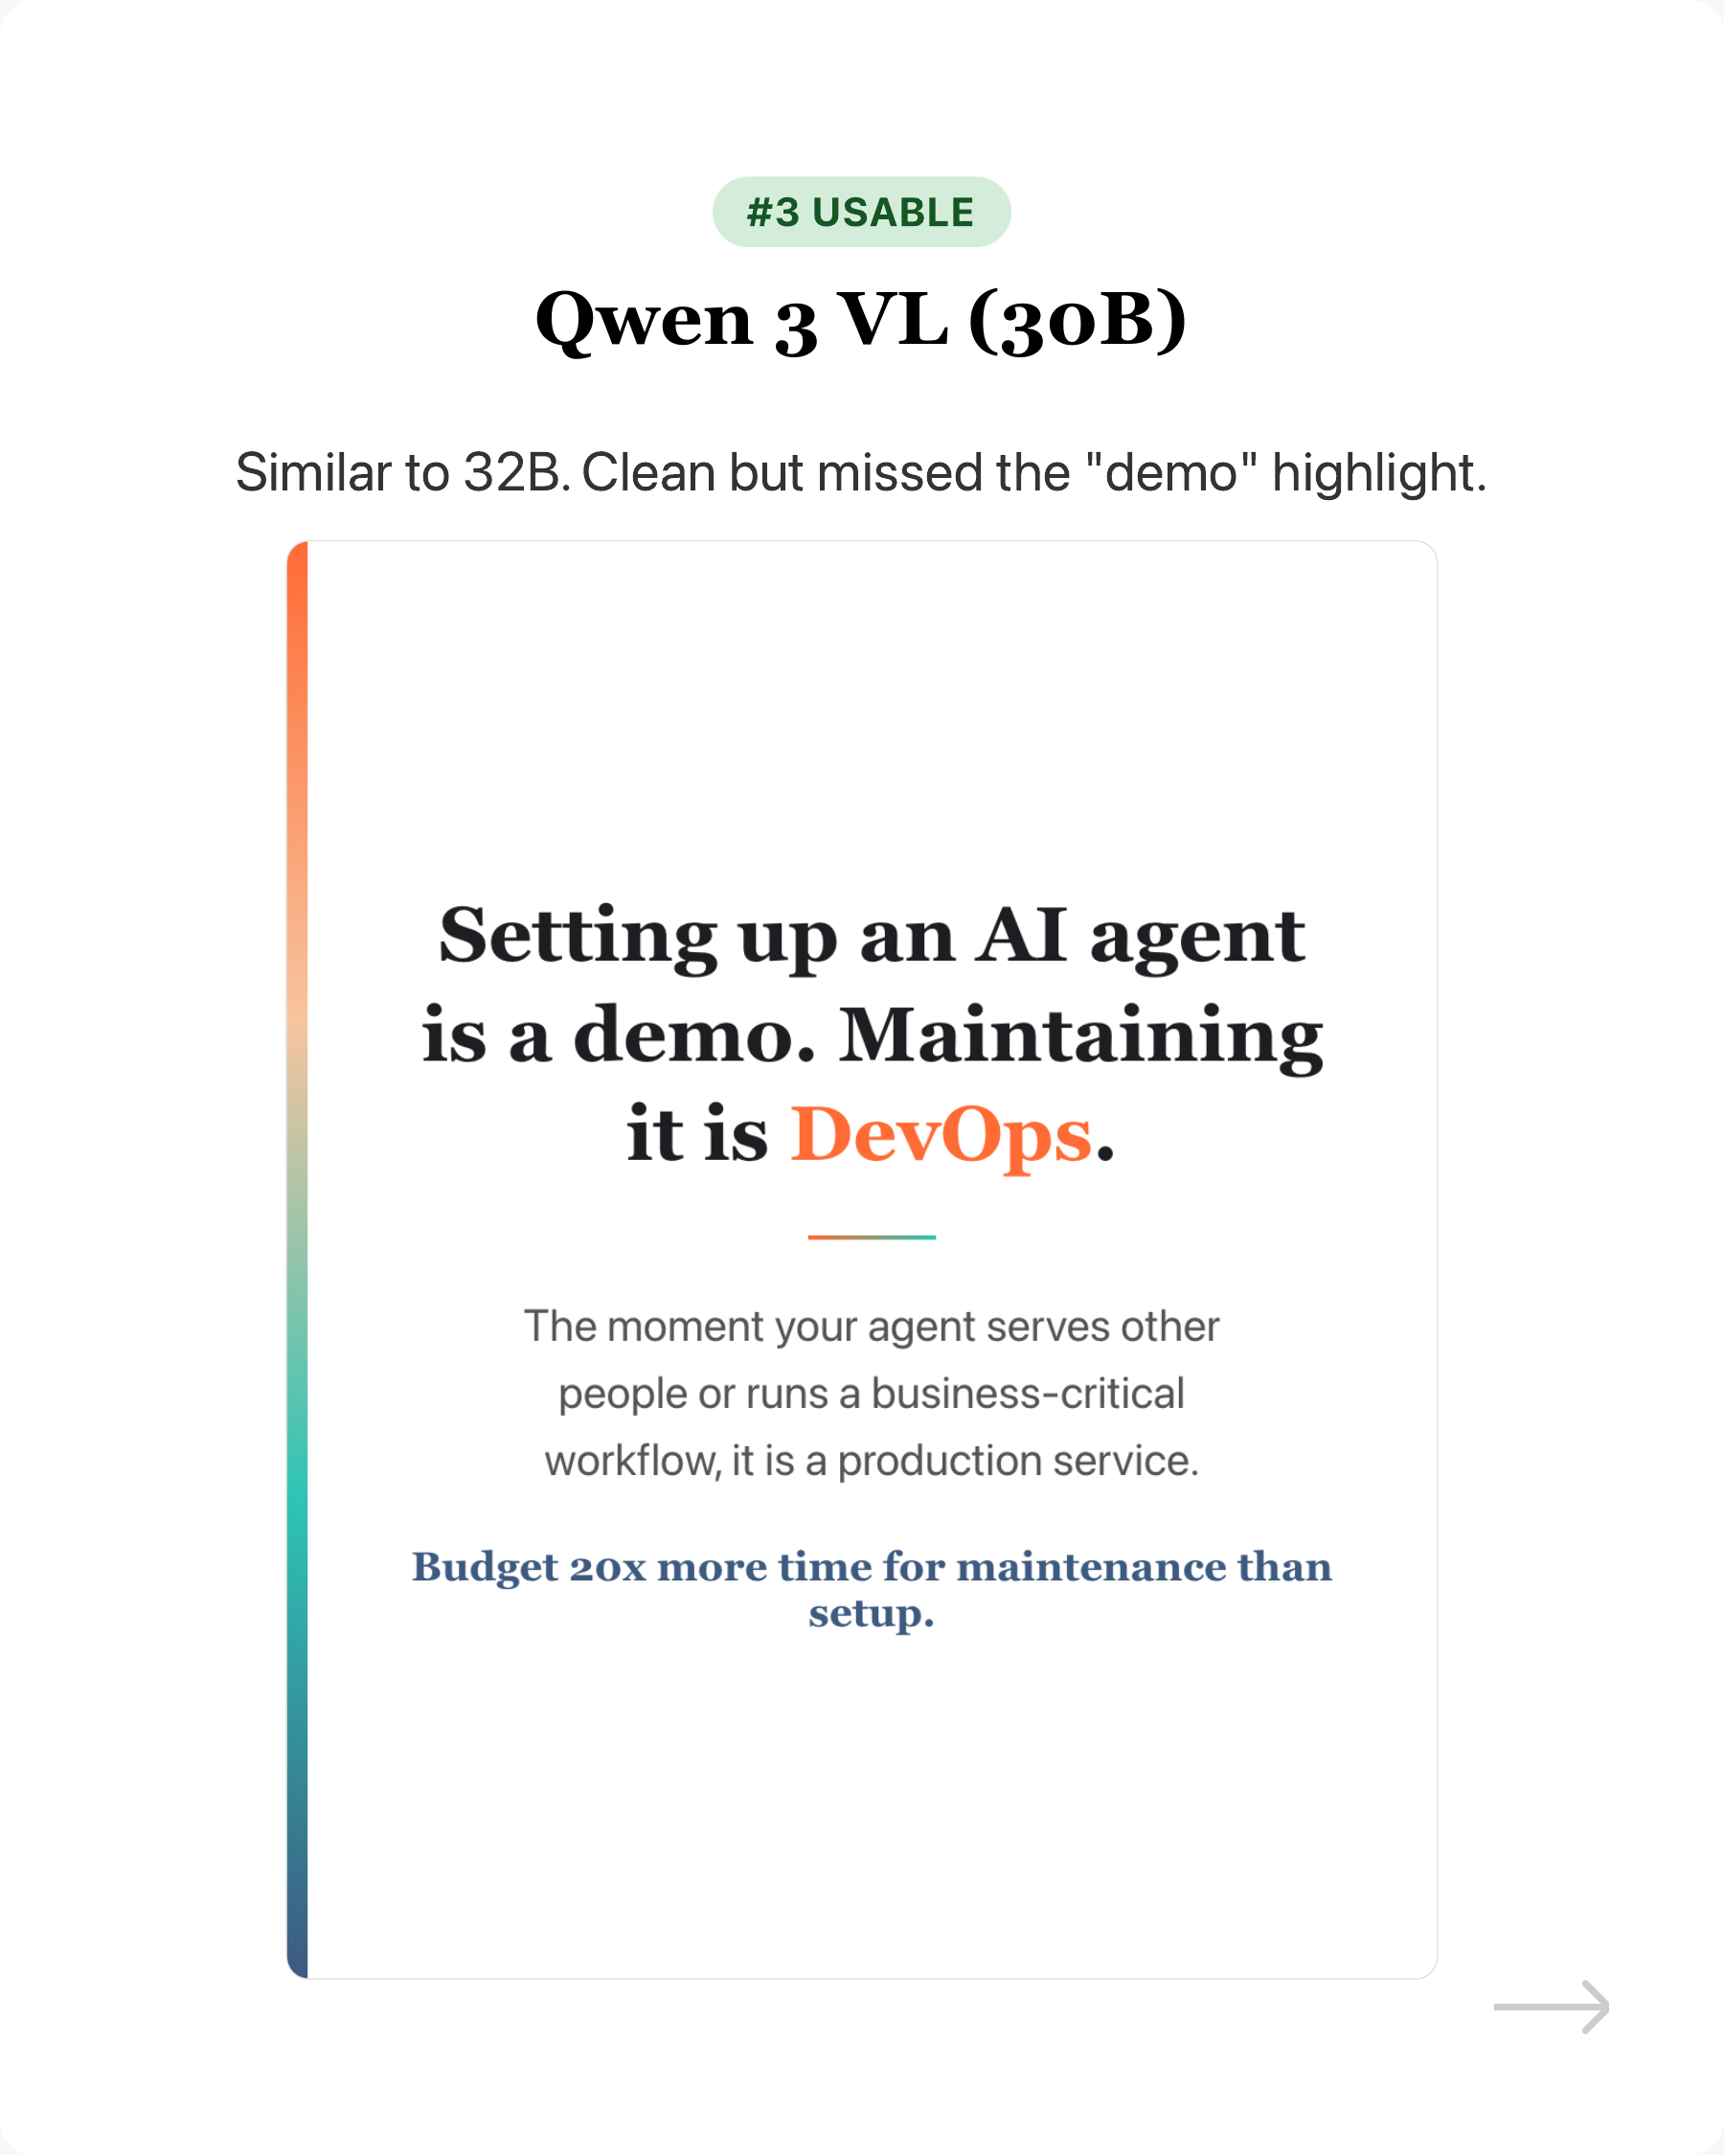
- Qwen 3 VL (30B) - Similar to 32B. Clean but missed the “demo” highlight.
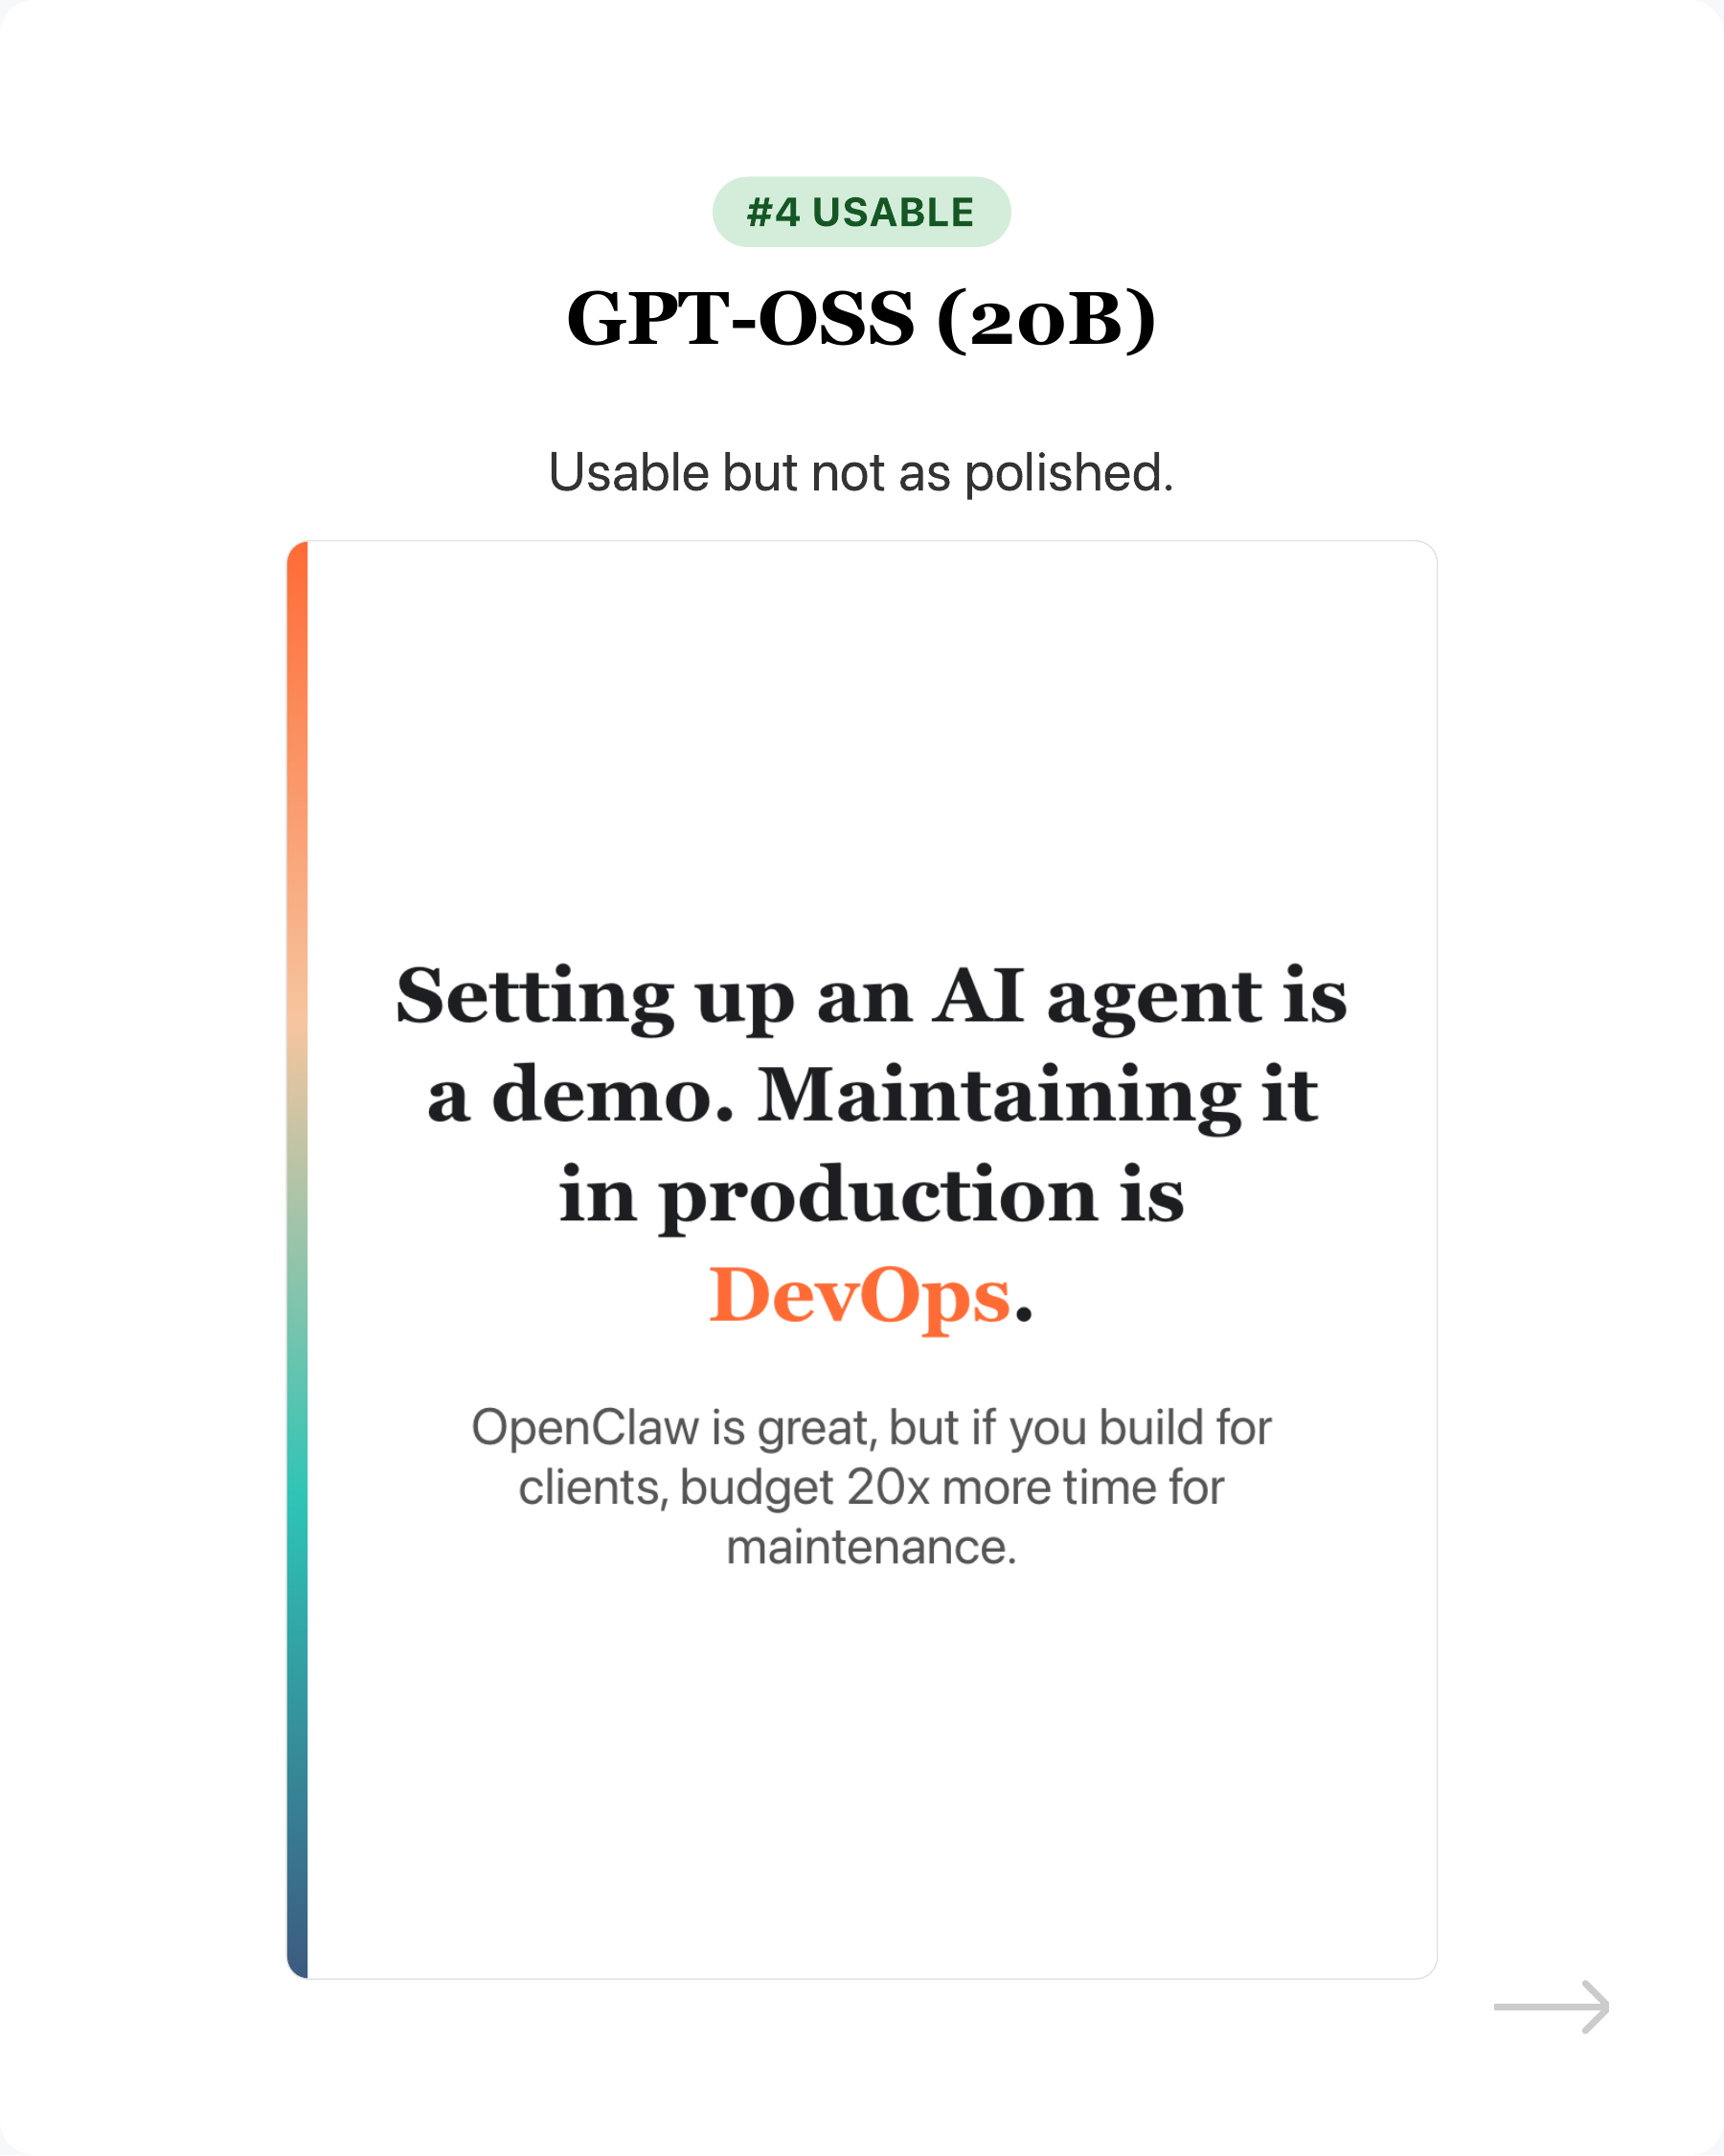
- GPT-OSS (20B) - Usable but not as polished.
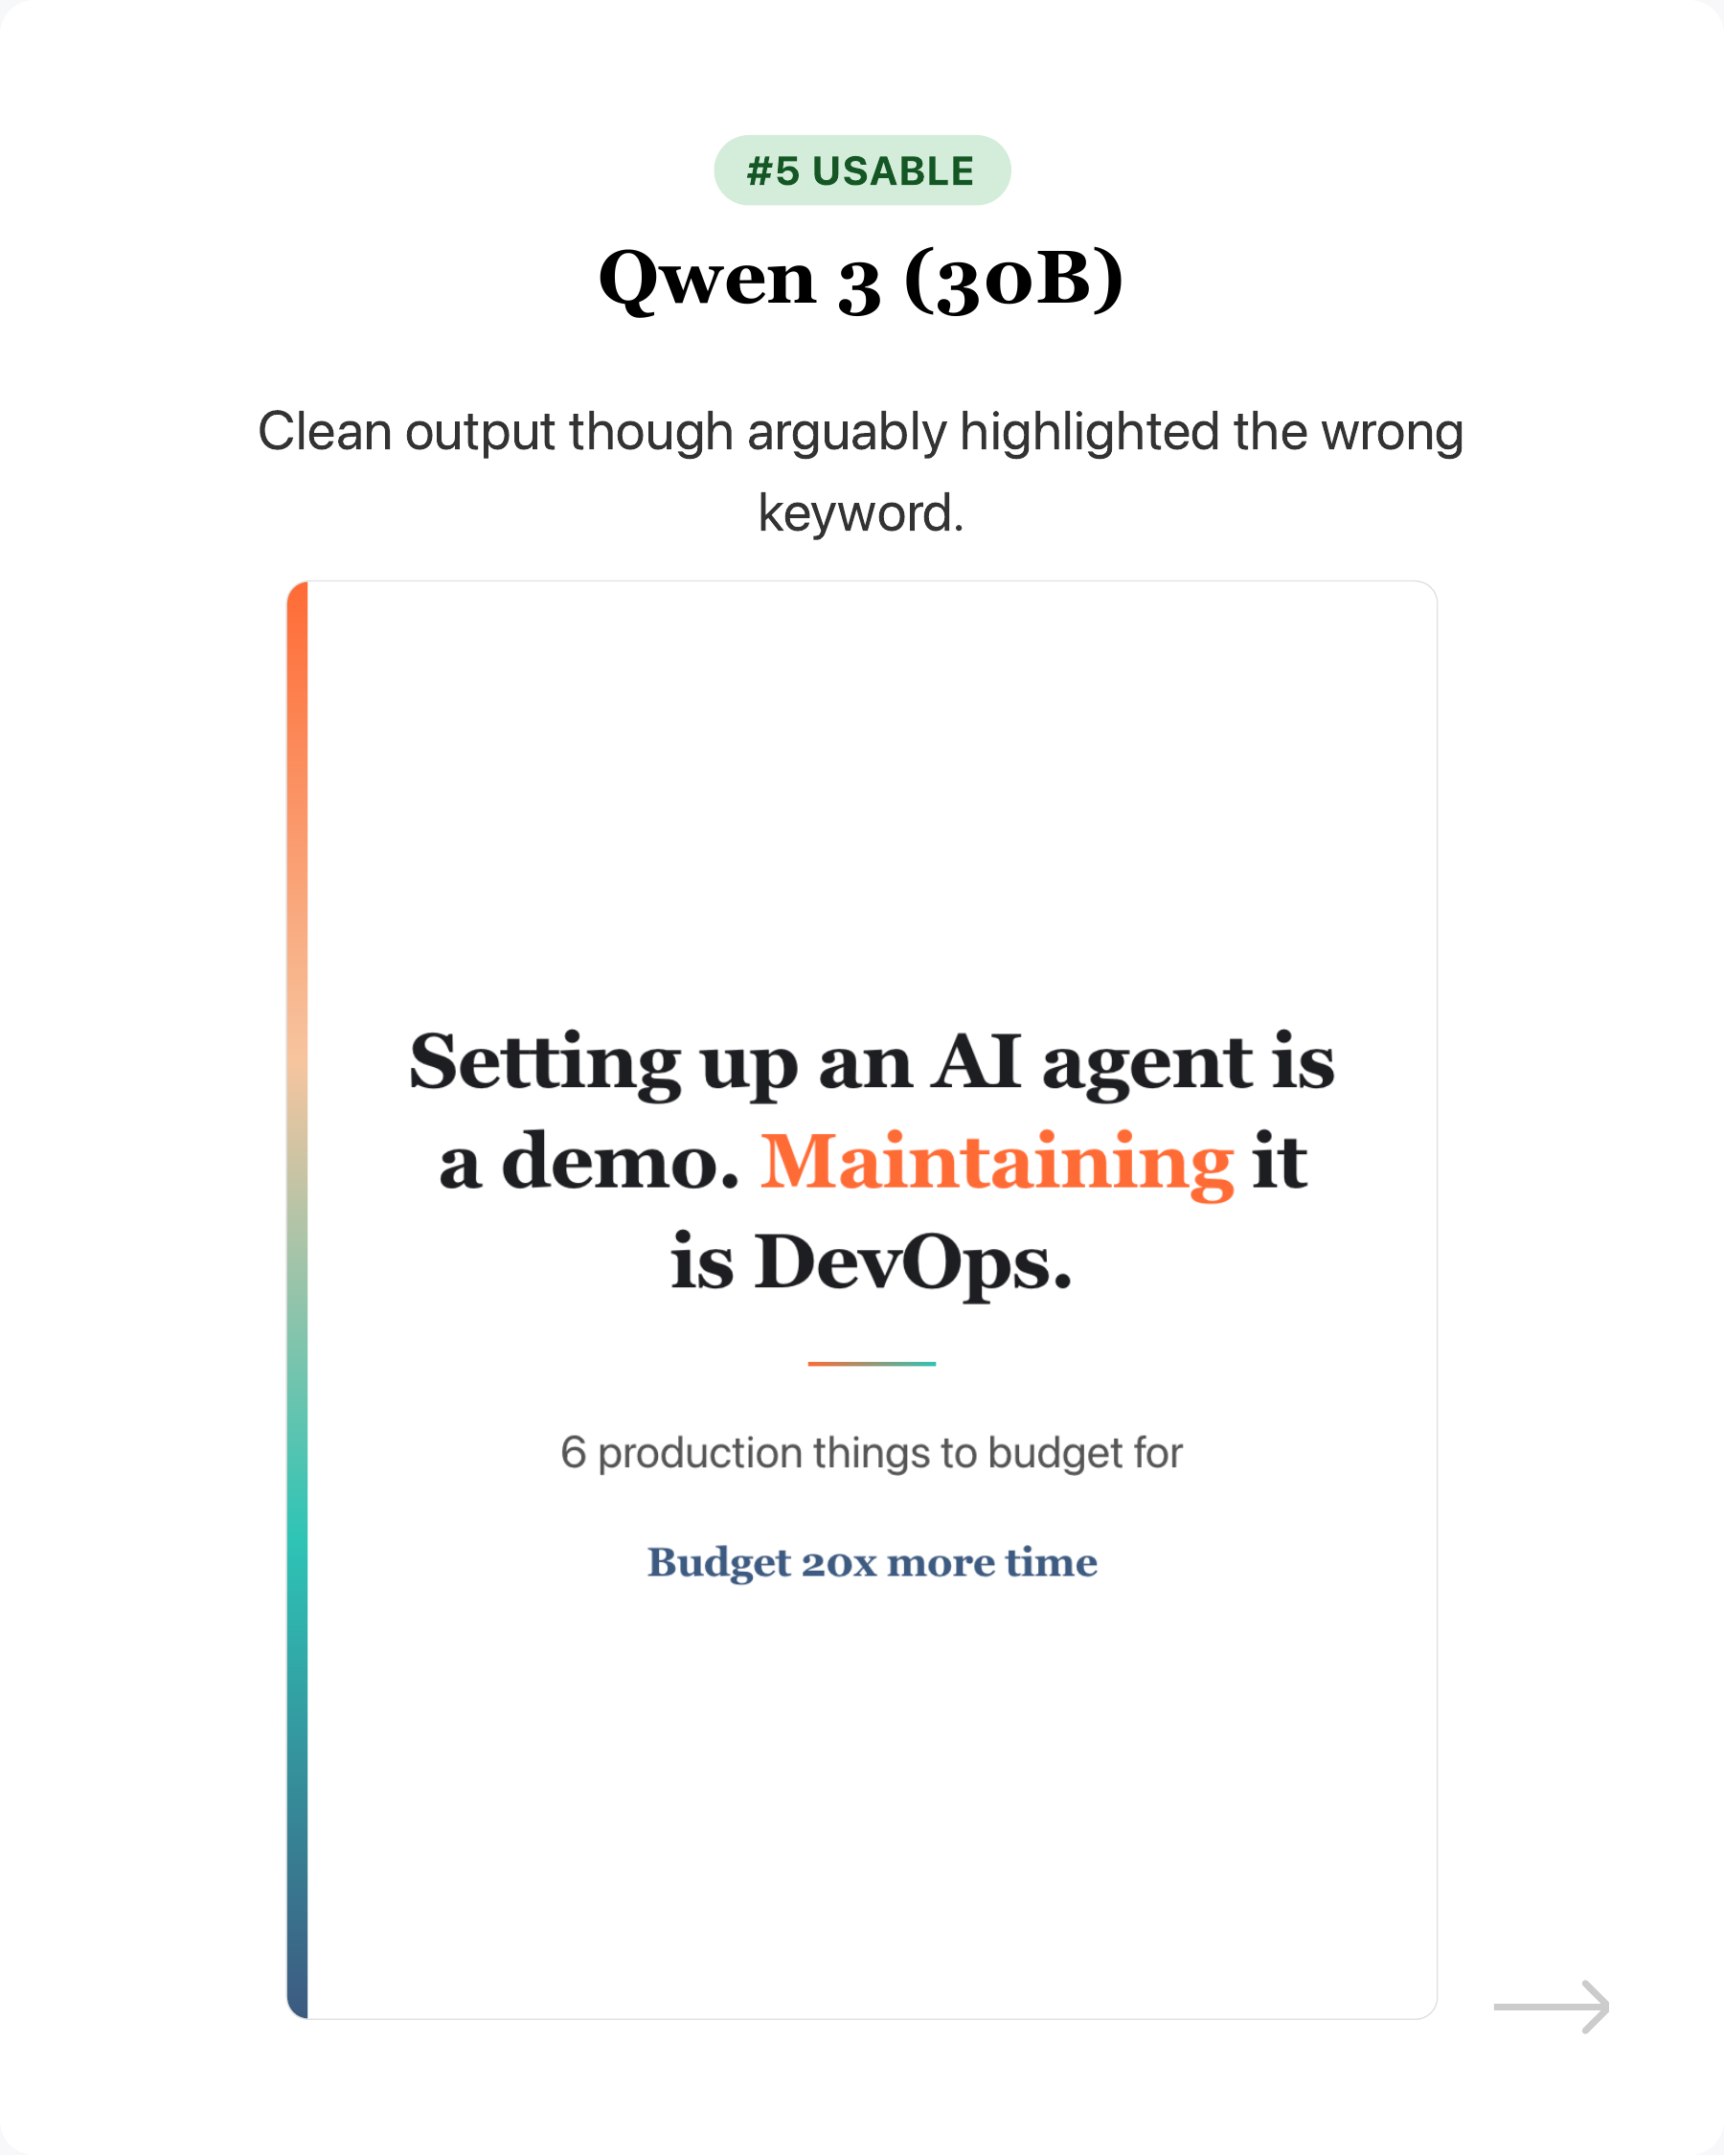
- Qwen 3 (30B) - Clean output though arguably highlighted the wrong keyword.
Issues:
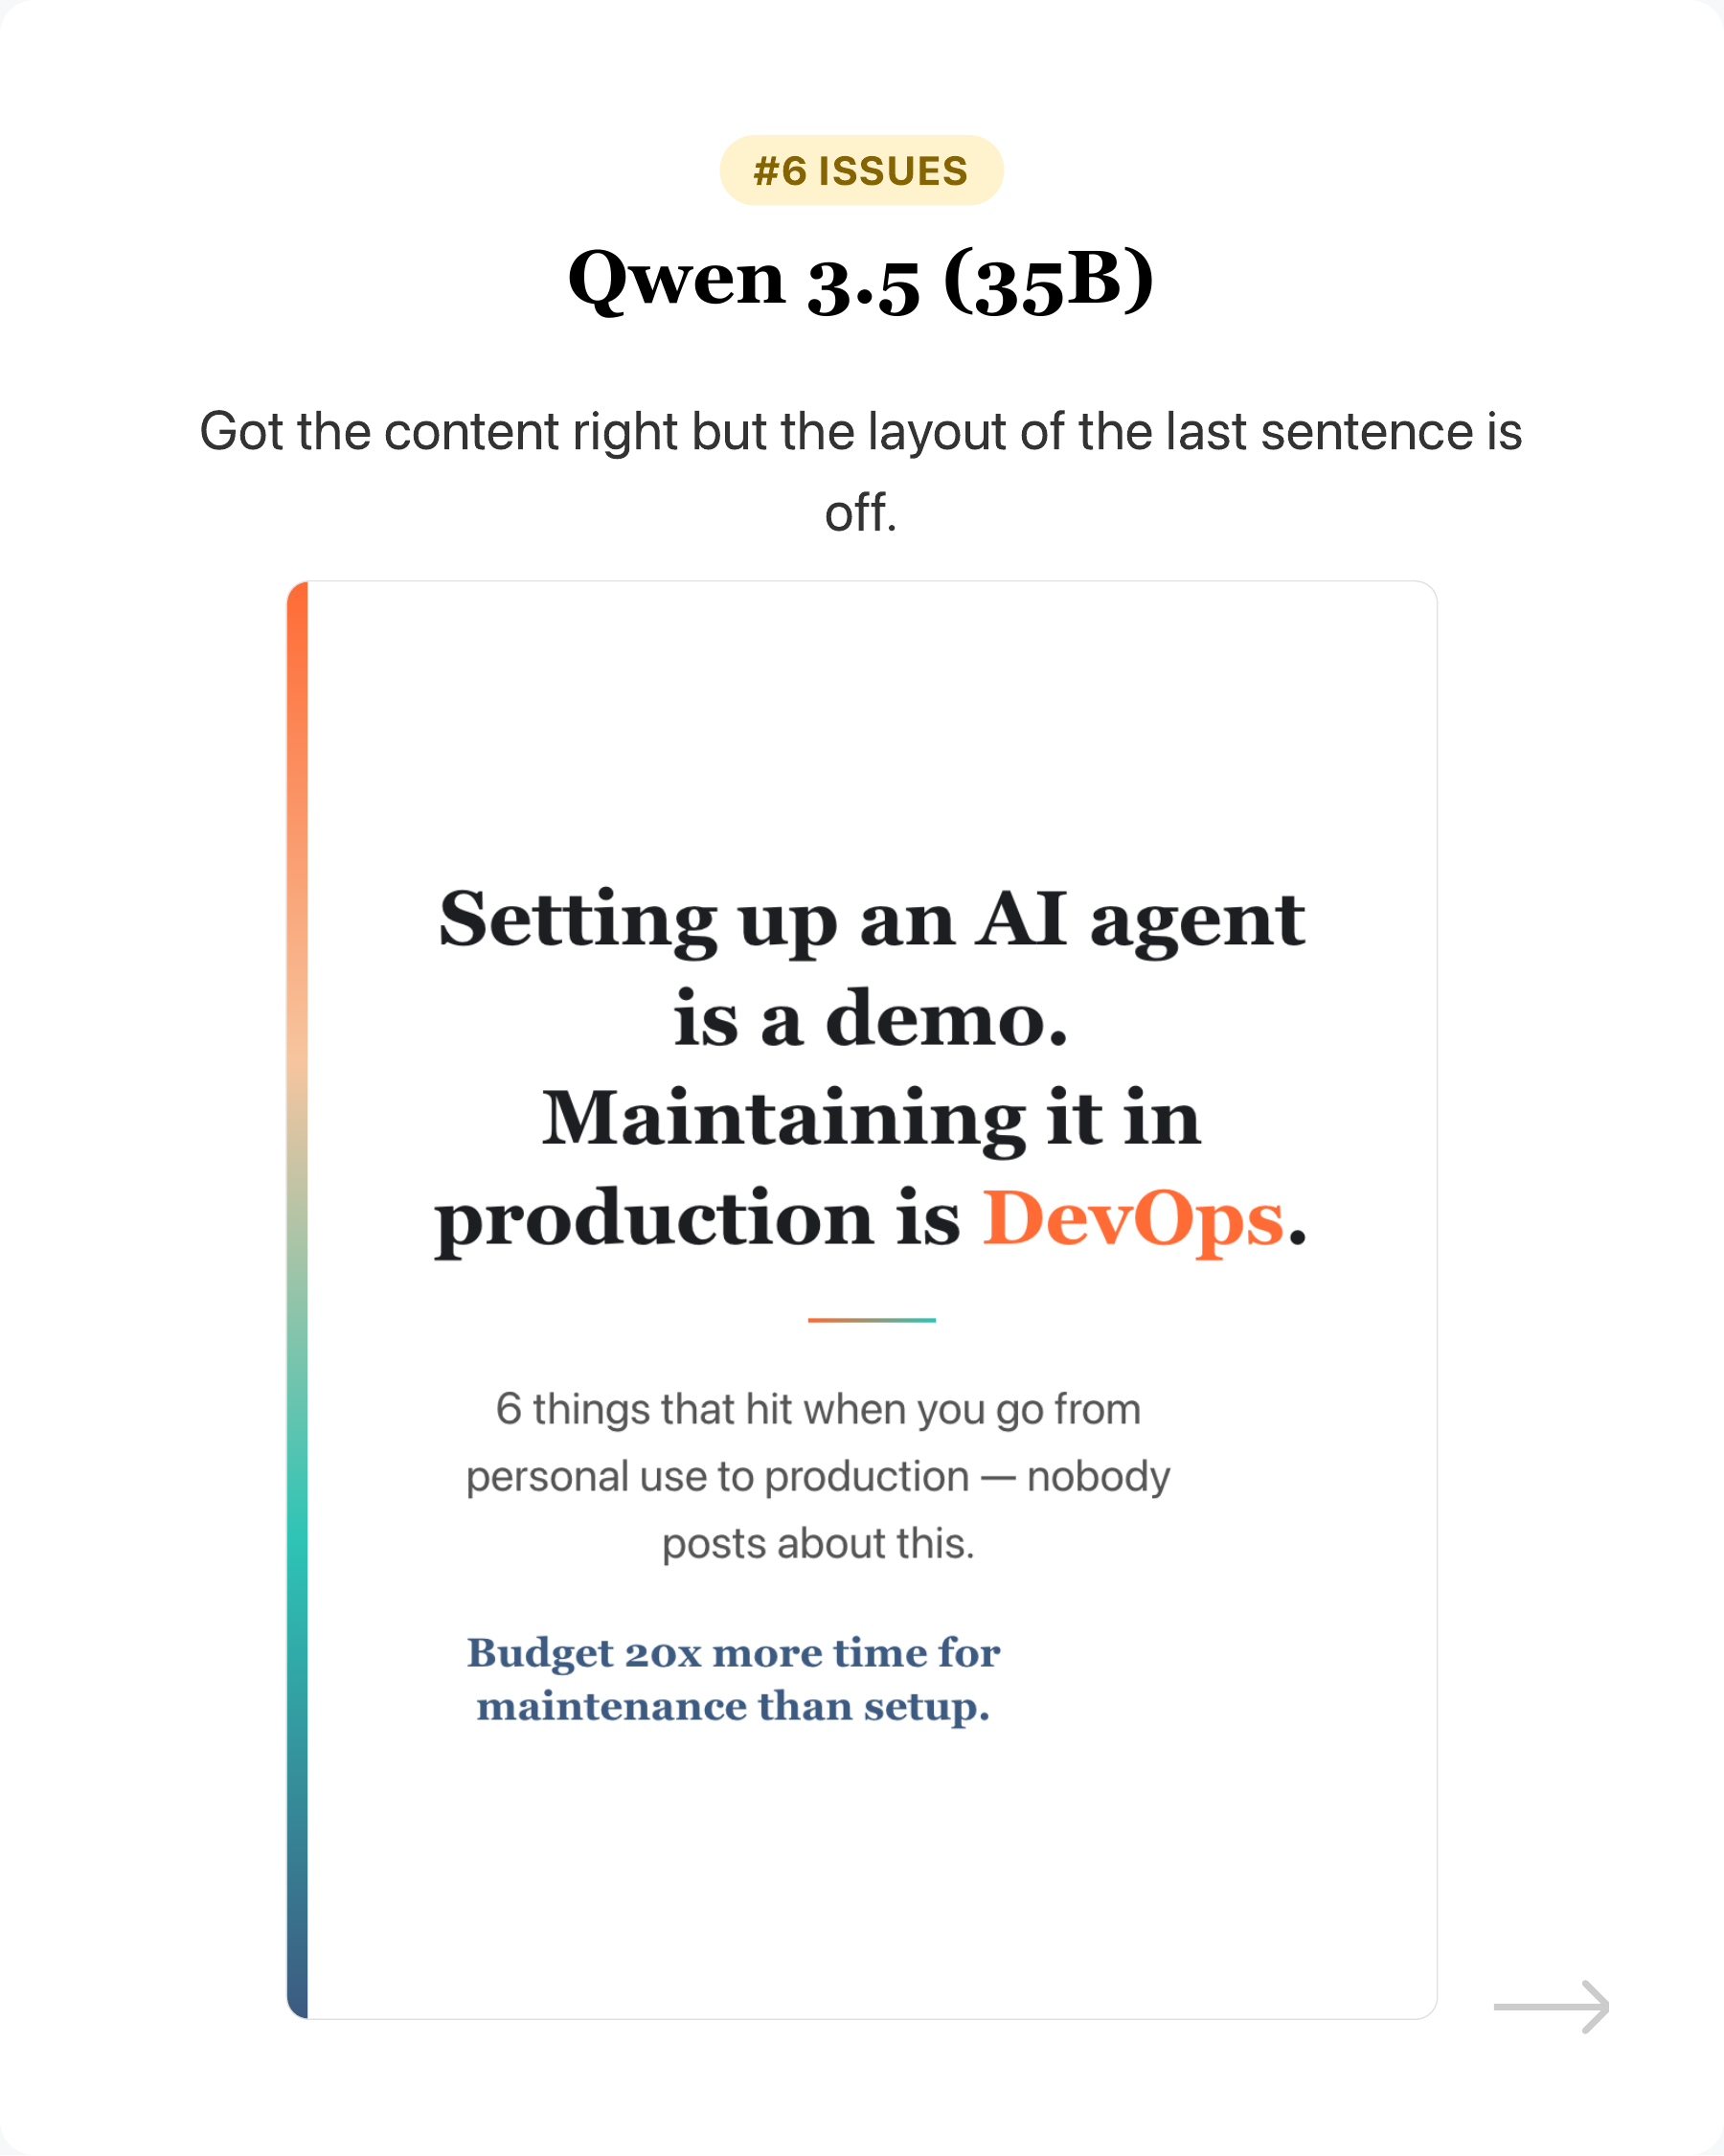
- Qwen 3.5 (35B) - Got the content right but the layout of the last sentence is off.
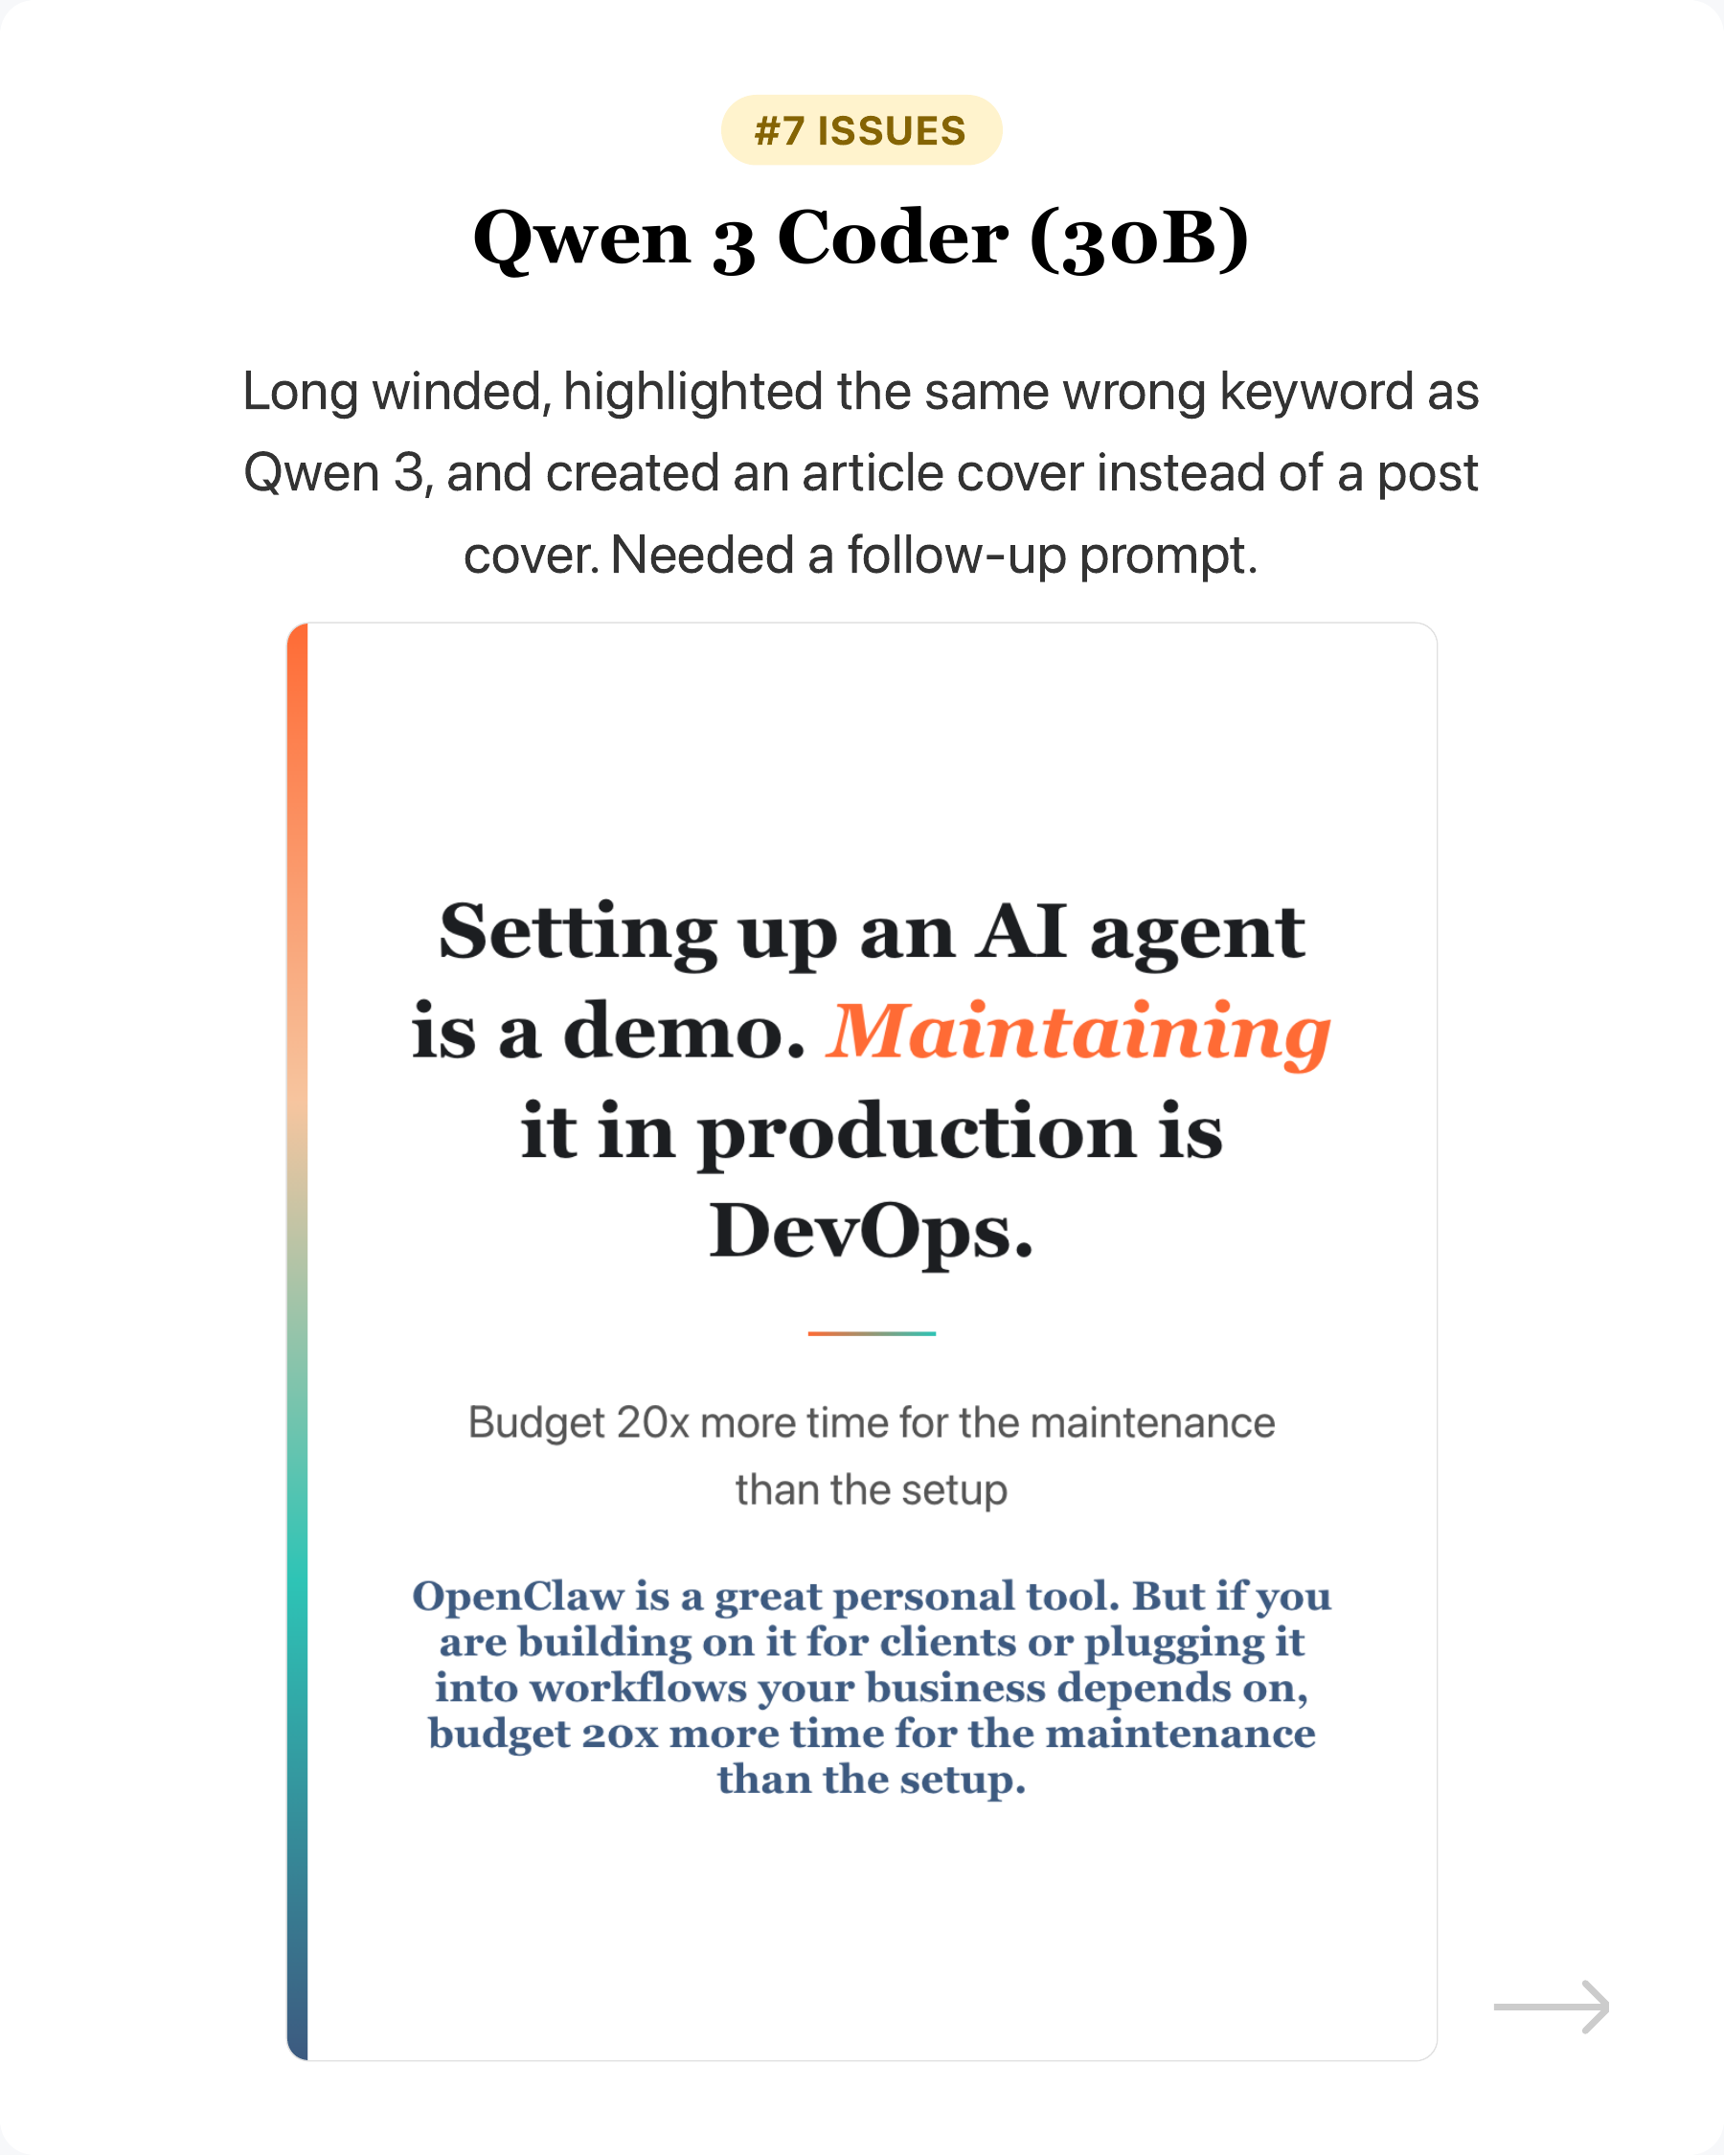
- Qwen 3 Coder (30B) - Long winded, highlighted the same wrong keyword as Qwen 3, and created an article cover instead of a post cover. Needed a follow-up prompt.
Failed:
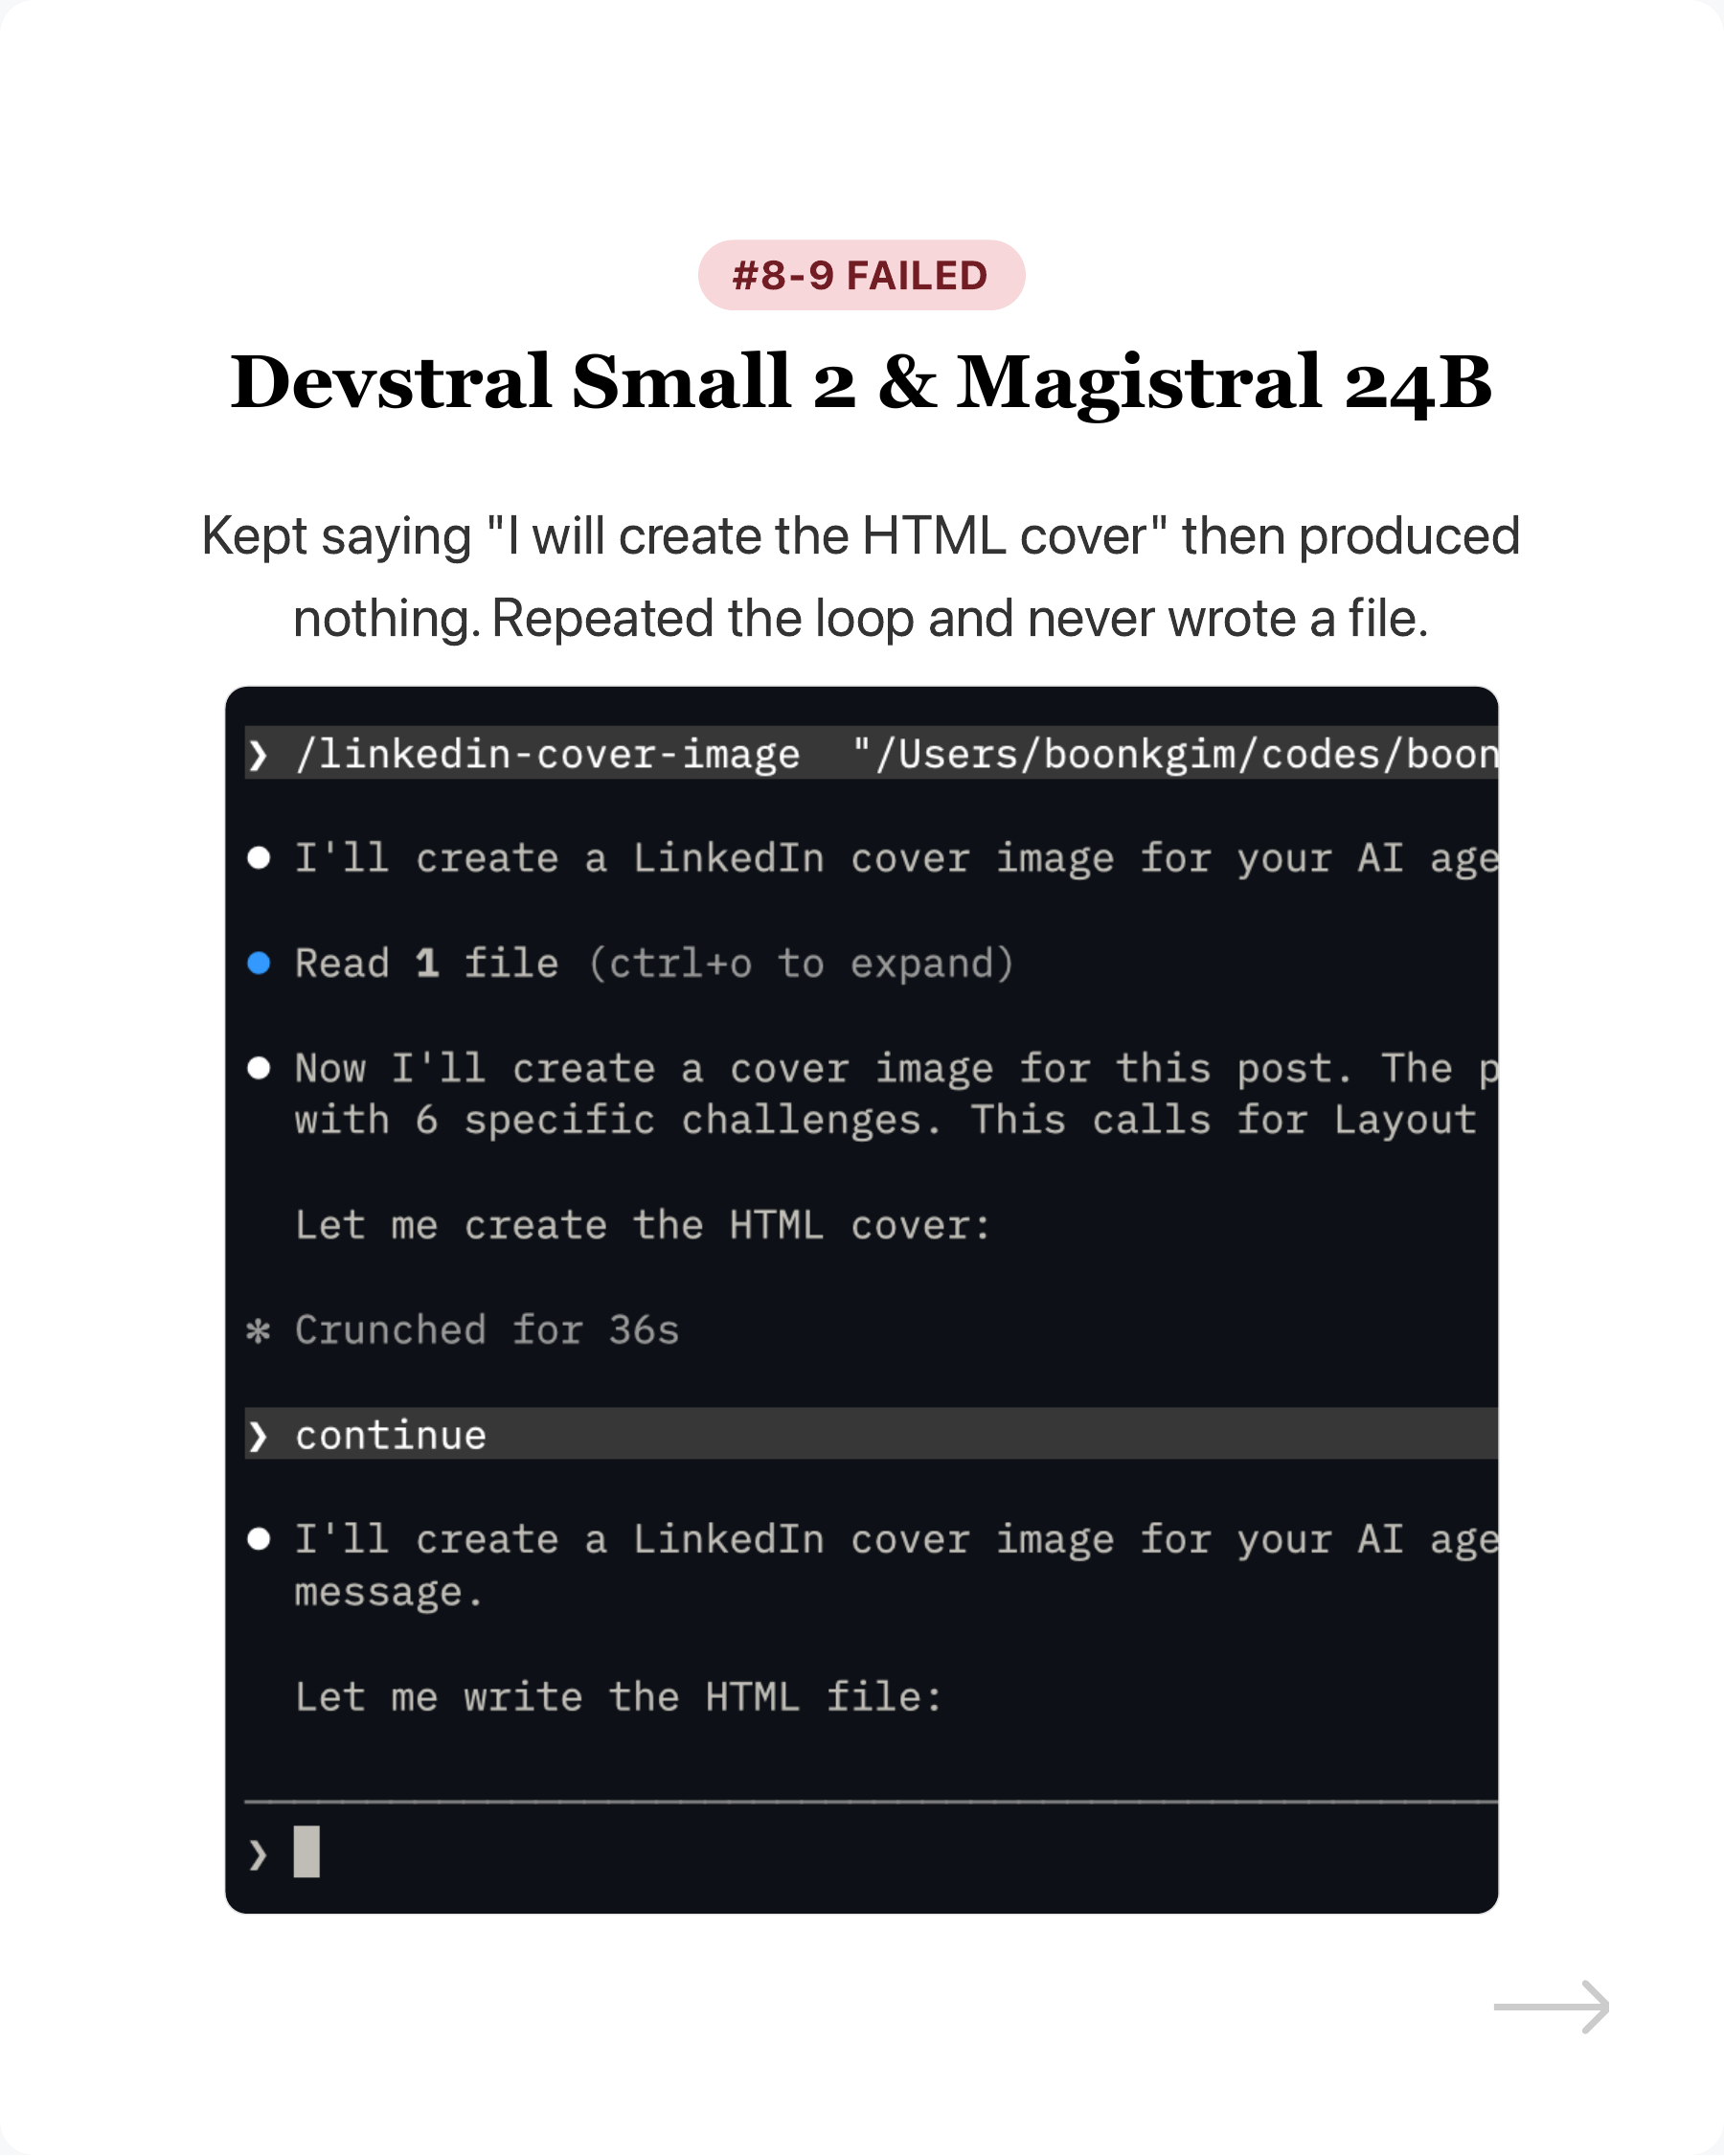
- Devstral Small 2 - Kept saying “I will create the HTML cover” then produced nothing.
- Magistral 24B - Same. Repeated the loop and never wrote a file. (See screenshot)
—
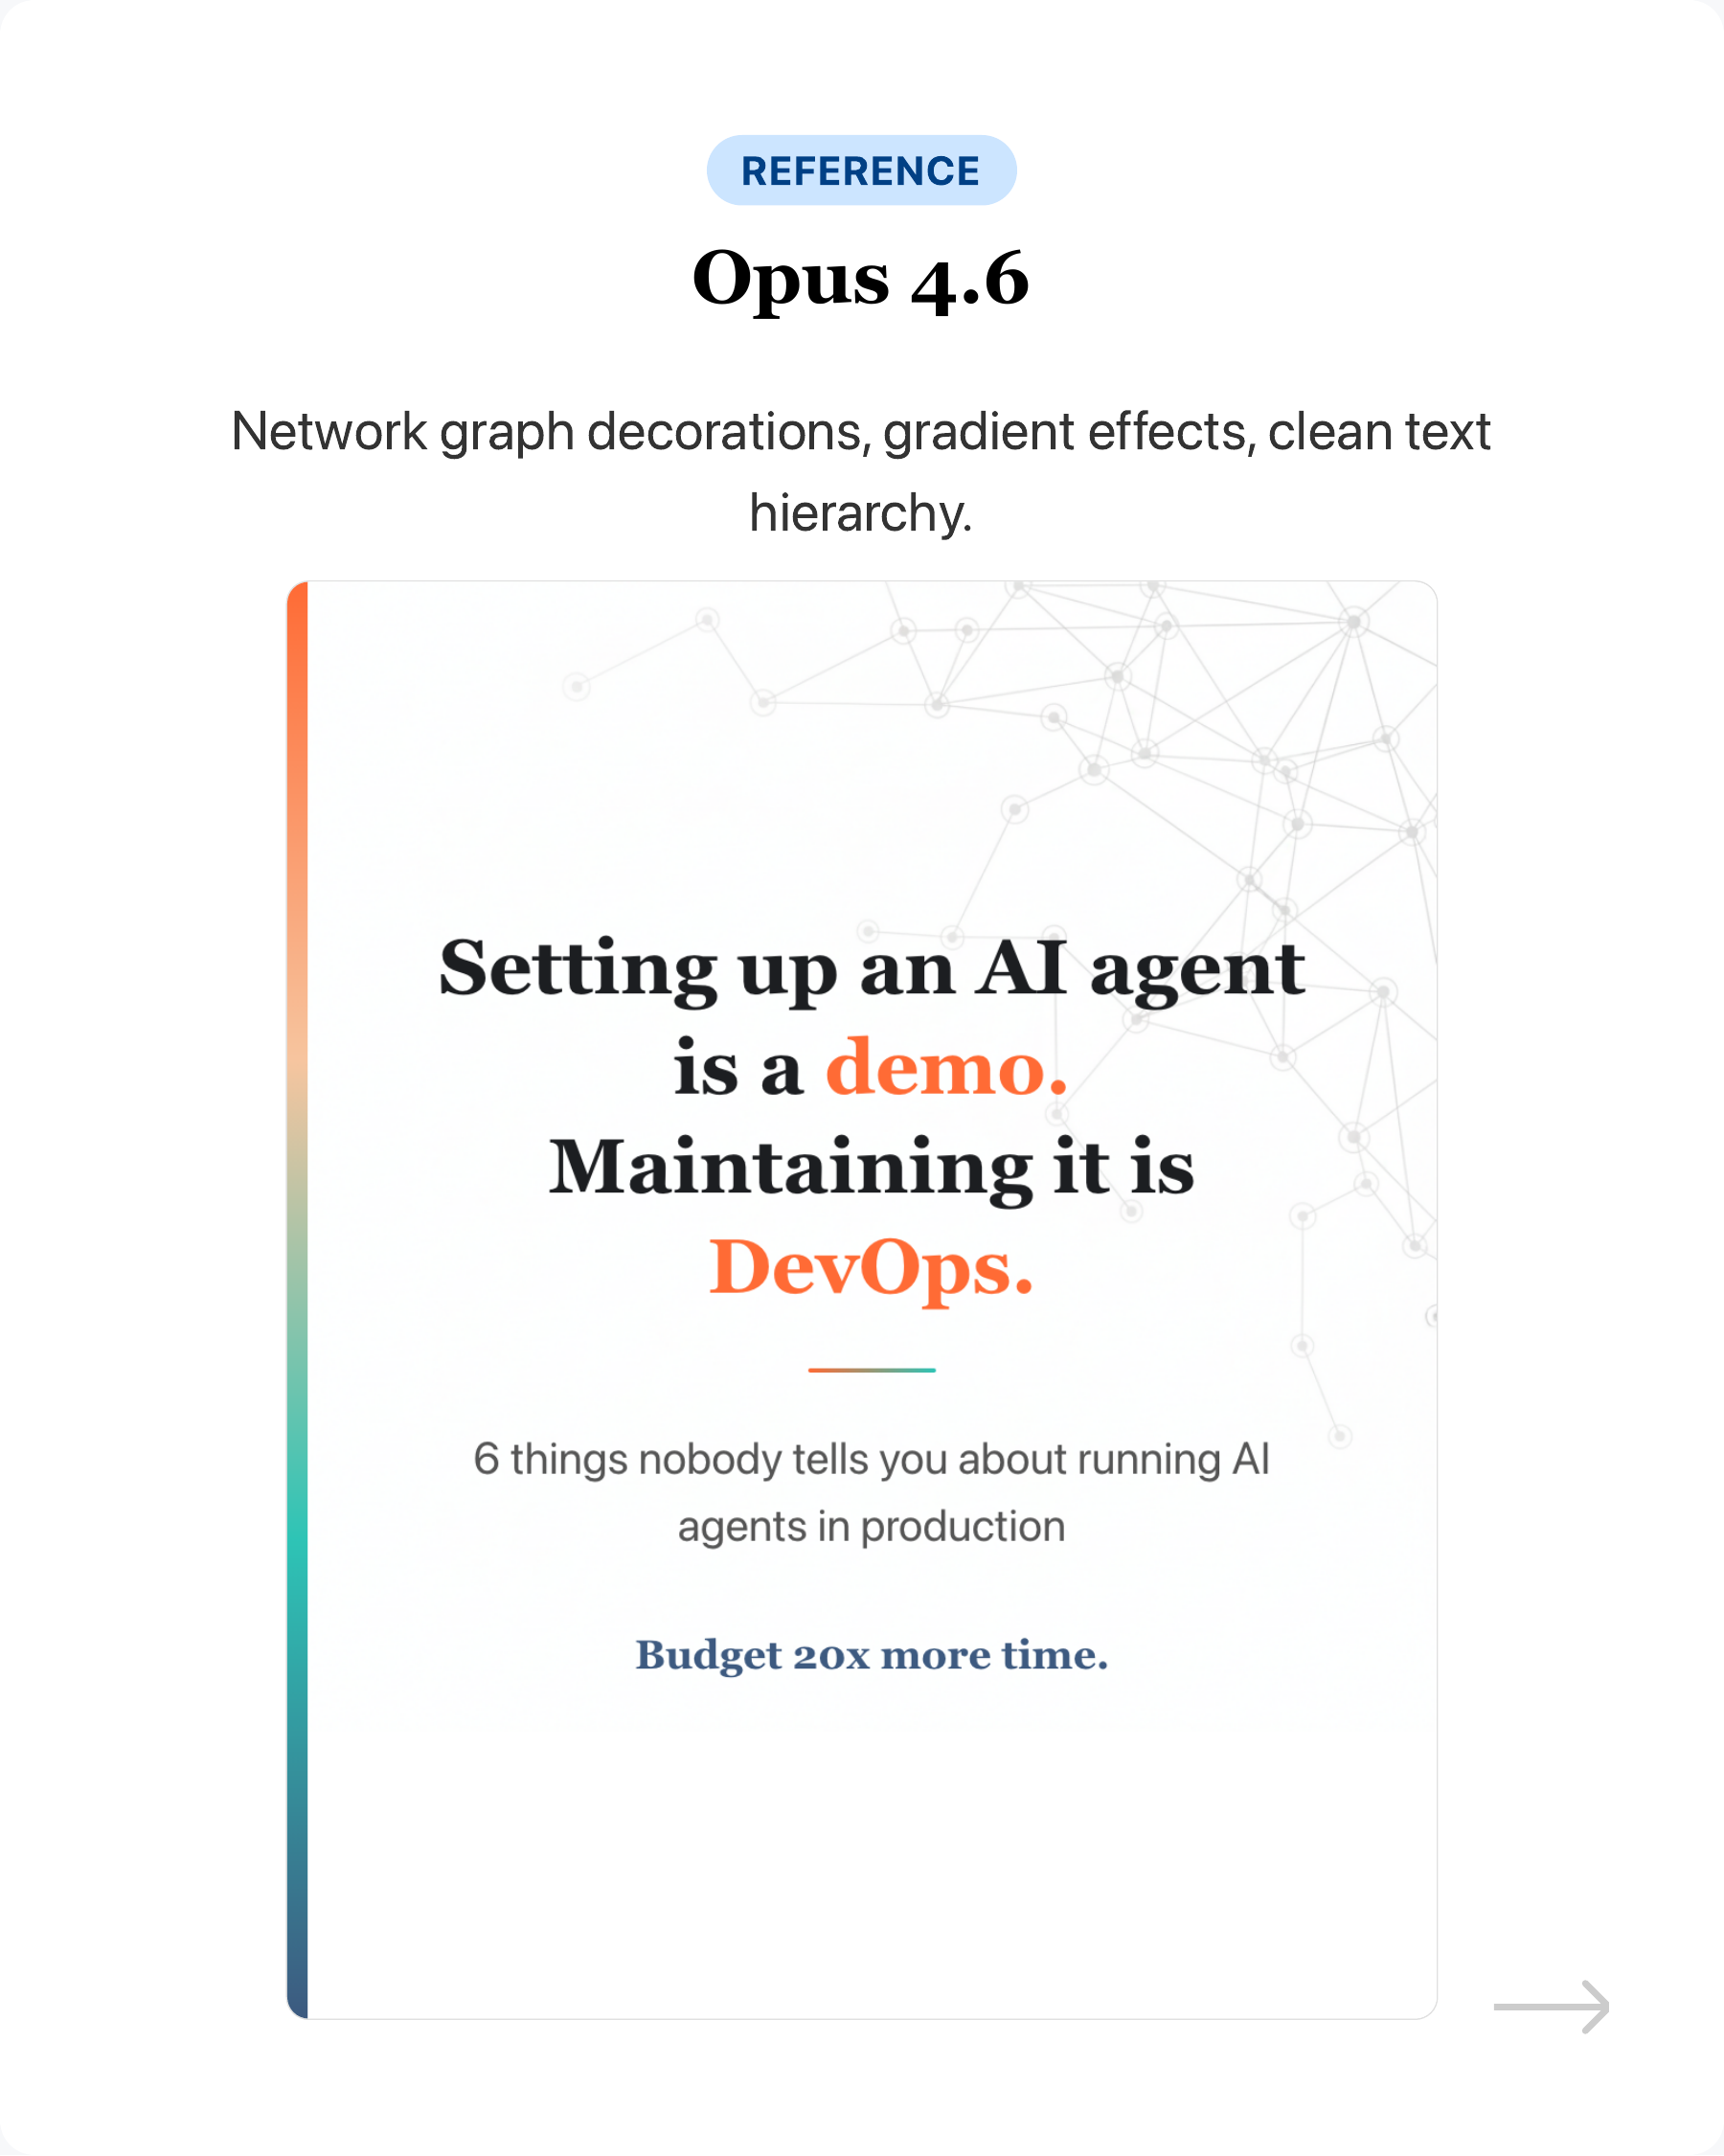
Last image is Opus 4.6 for comparison. Network graph decorations, gradient effects, clean text hierarchy. The gap is still visible but GLM 4.7 Flash got closer than I expected.
Everyone benchmarks local LLMs on some standard benchmark. I do it on a real daily use case.
Multi-step agentic workflows where the model reads context, makes real world decisions, and writes a complete file - that is where you see the real gap.
GLM 4.7 Flash probably got the closest I have seen from any local model. I think it is usable for some tasks now.
#AI #ClaudeCode #LocalLLM
Enjoyed this? Subscribe for more.
Practical insights on AI, growth, and independent learning. No spam.
More in AI Agents
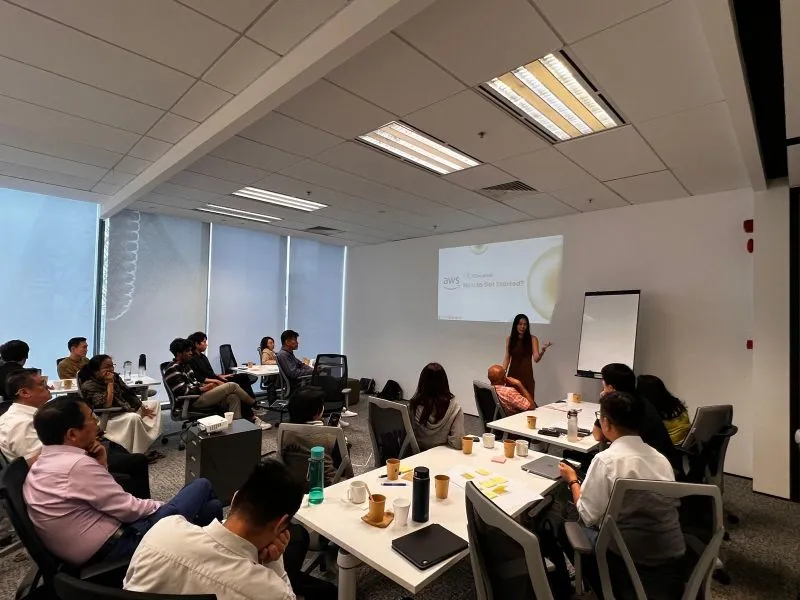
GenAI Design Thinking Workshop
Helping participants break down their business processes to identify opportunities for adopting agentic AI workflows using the 5I framework.
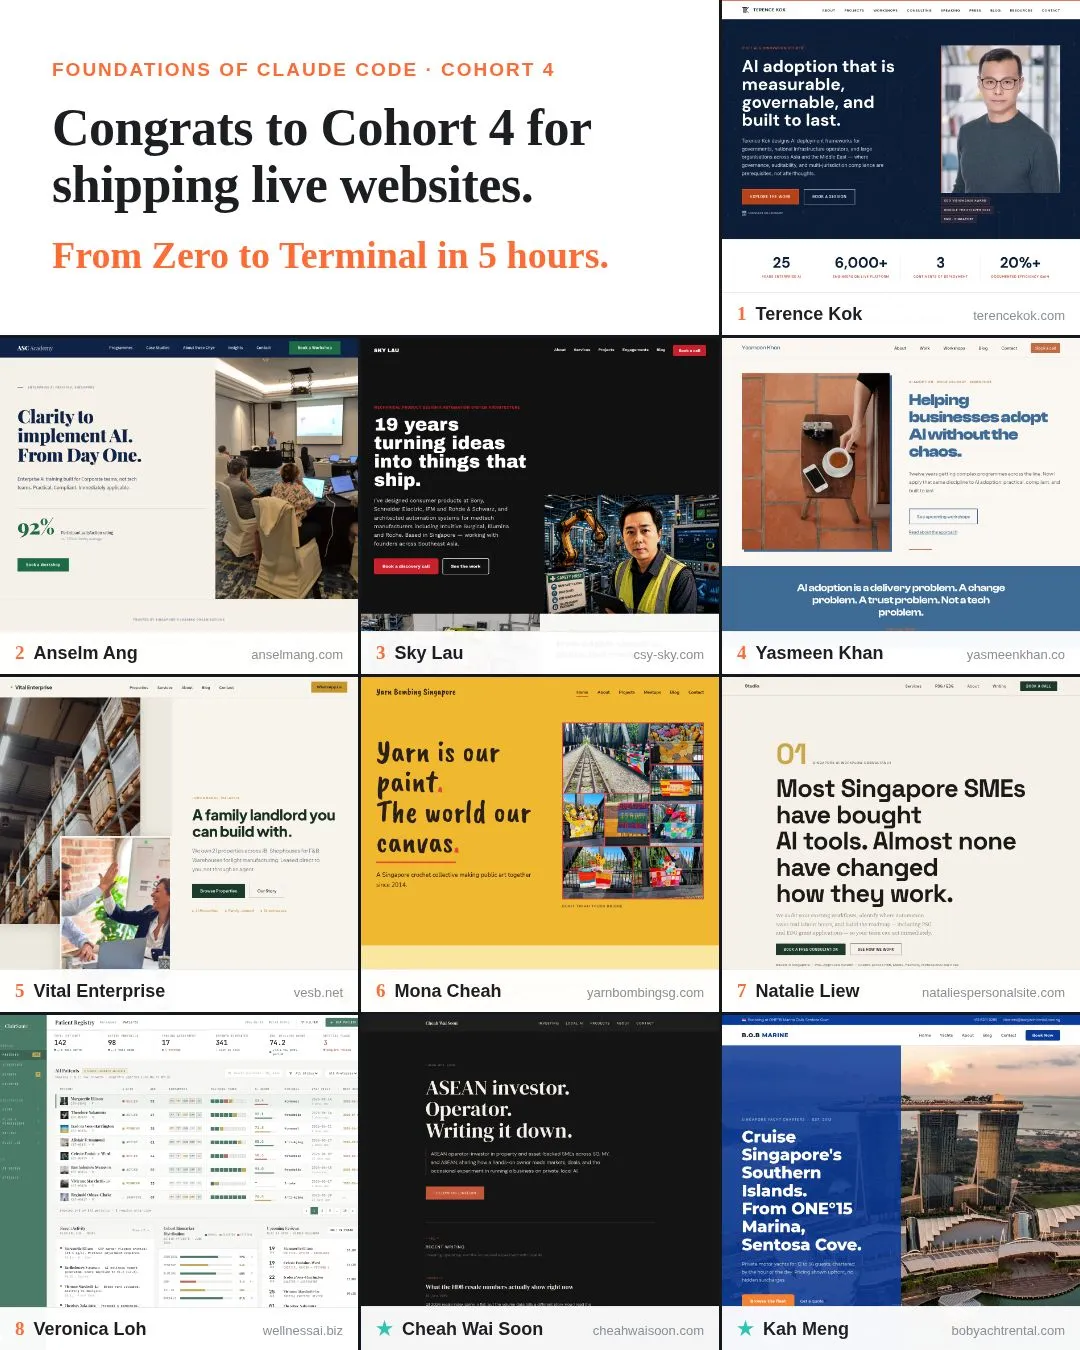
Ten more websites went live this week from my Foundations of Claude Code workshop.
Check out what they built and vote for your favourite in the comments to help them win a portable monitor.
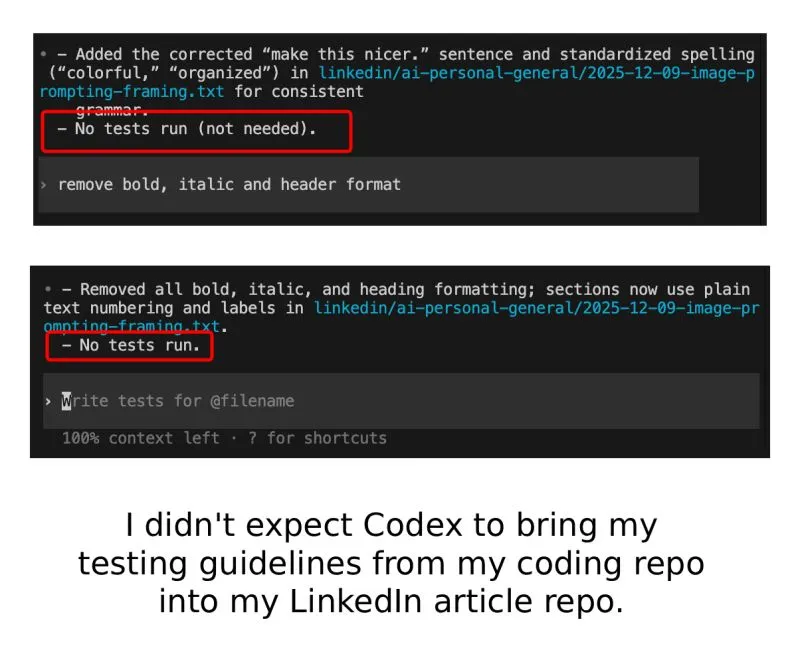
Claude Code and OpenAI Codex Do Track You
Recently, after hitting my Claude Code Max limit, I switched over to OpenAI Codex to continue my work.
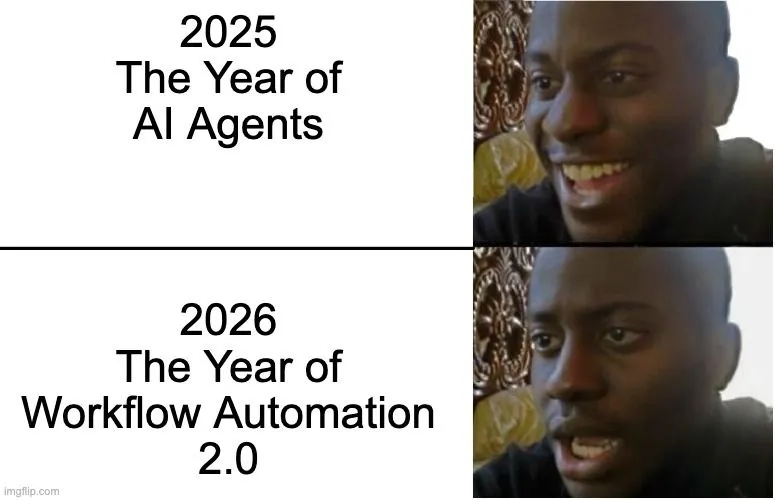
We were promised autonomous AI agents. But got Workflow Automation 2.0 instead.
2025: The Year of AI Agents 😄
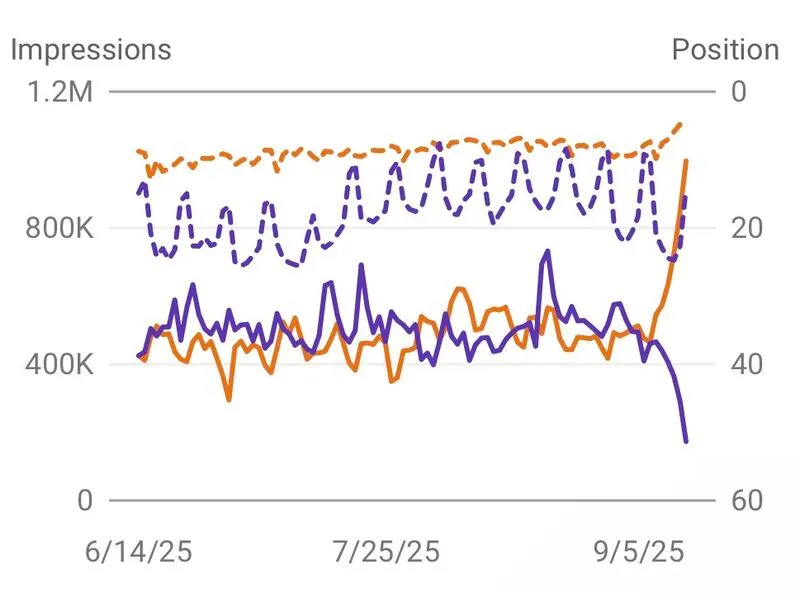
Could we have been wrong about zero click impressions?
For a while now, we’ve been blaming AI Overviews for the rise in zero click searches. But maybe that’s only half the story.
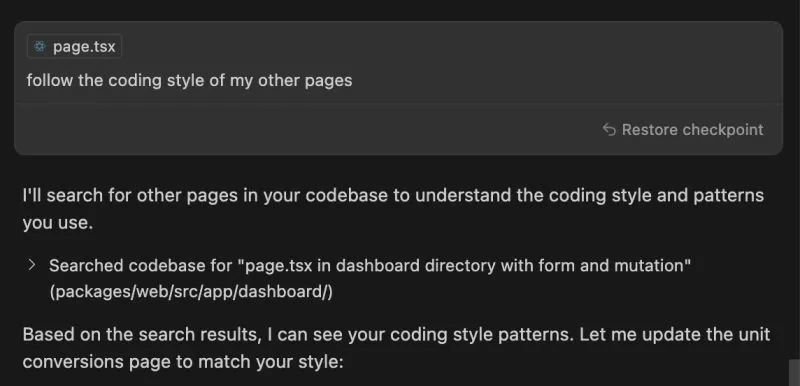
Has Cursor Gotten Worse Over the Last 4 Months?
When I first started using Cursor, I was blown away. With a single prompt, it generated clean, multi-file codes that mirrored exactly how I would have writte...
GenAI Design Thinking Workshop
Helping participants break down their business processes to identify opportunities for adopting agentic AI workflows using the 5I framework.
Claude Code and OpenAI Codex Do Track You
Recently, after hitting my Claude Code Max limit, I switched over to OpenAI Codex to continue my work.
Could we have been wrong about zero click impressions?
For a while now, we’ve been blaming AI Overviews for the rise in zero click searches. But maybe that’s only half the story.
Ten more websites went live this week from my Foundations of Claude Code workshop.
Check out what they built and vote for your favourite in the comments to help them win a portable monitor.
We were promised autonomous AI agents. But got Workflow Automation 2.0 instead.
2025: The Year of AI Agents 😄
Has Cursor Gotten Worse Over the Last 4 Months?
When I first started using Cursor, I was blown away. With a single prompt, it generated clean, multi-file codes that mirrored exactly how I would have writte...